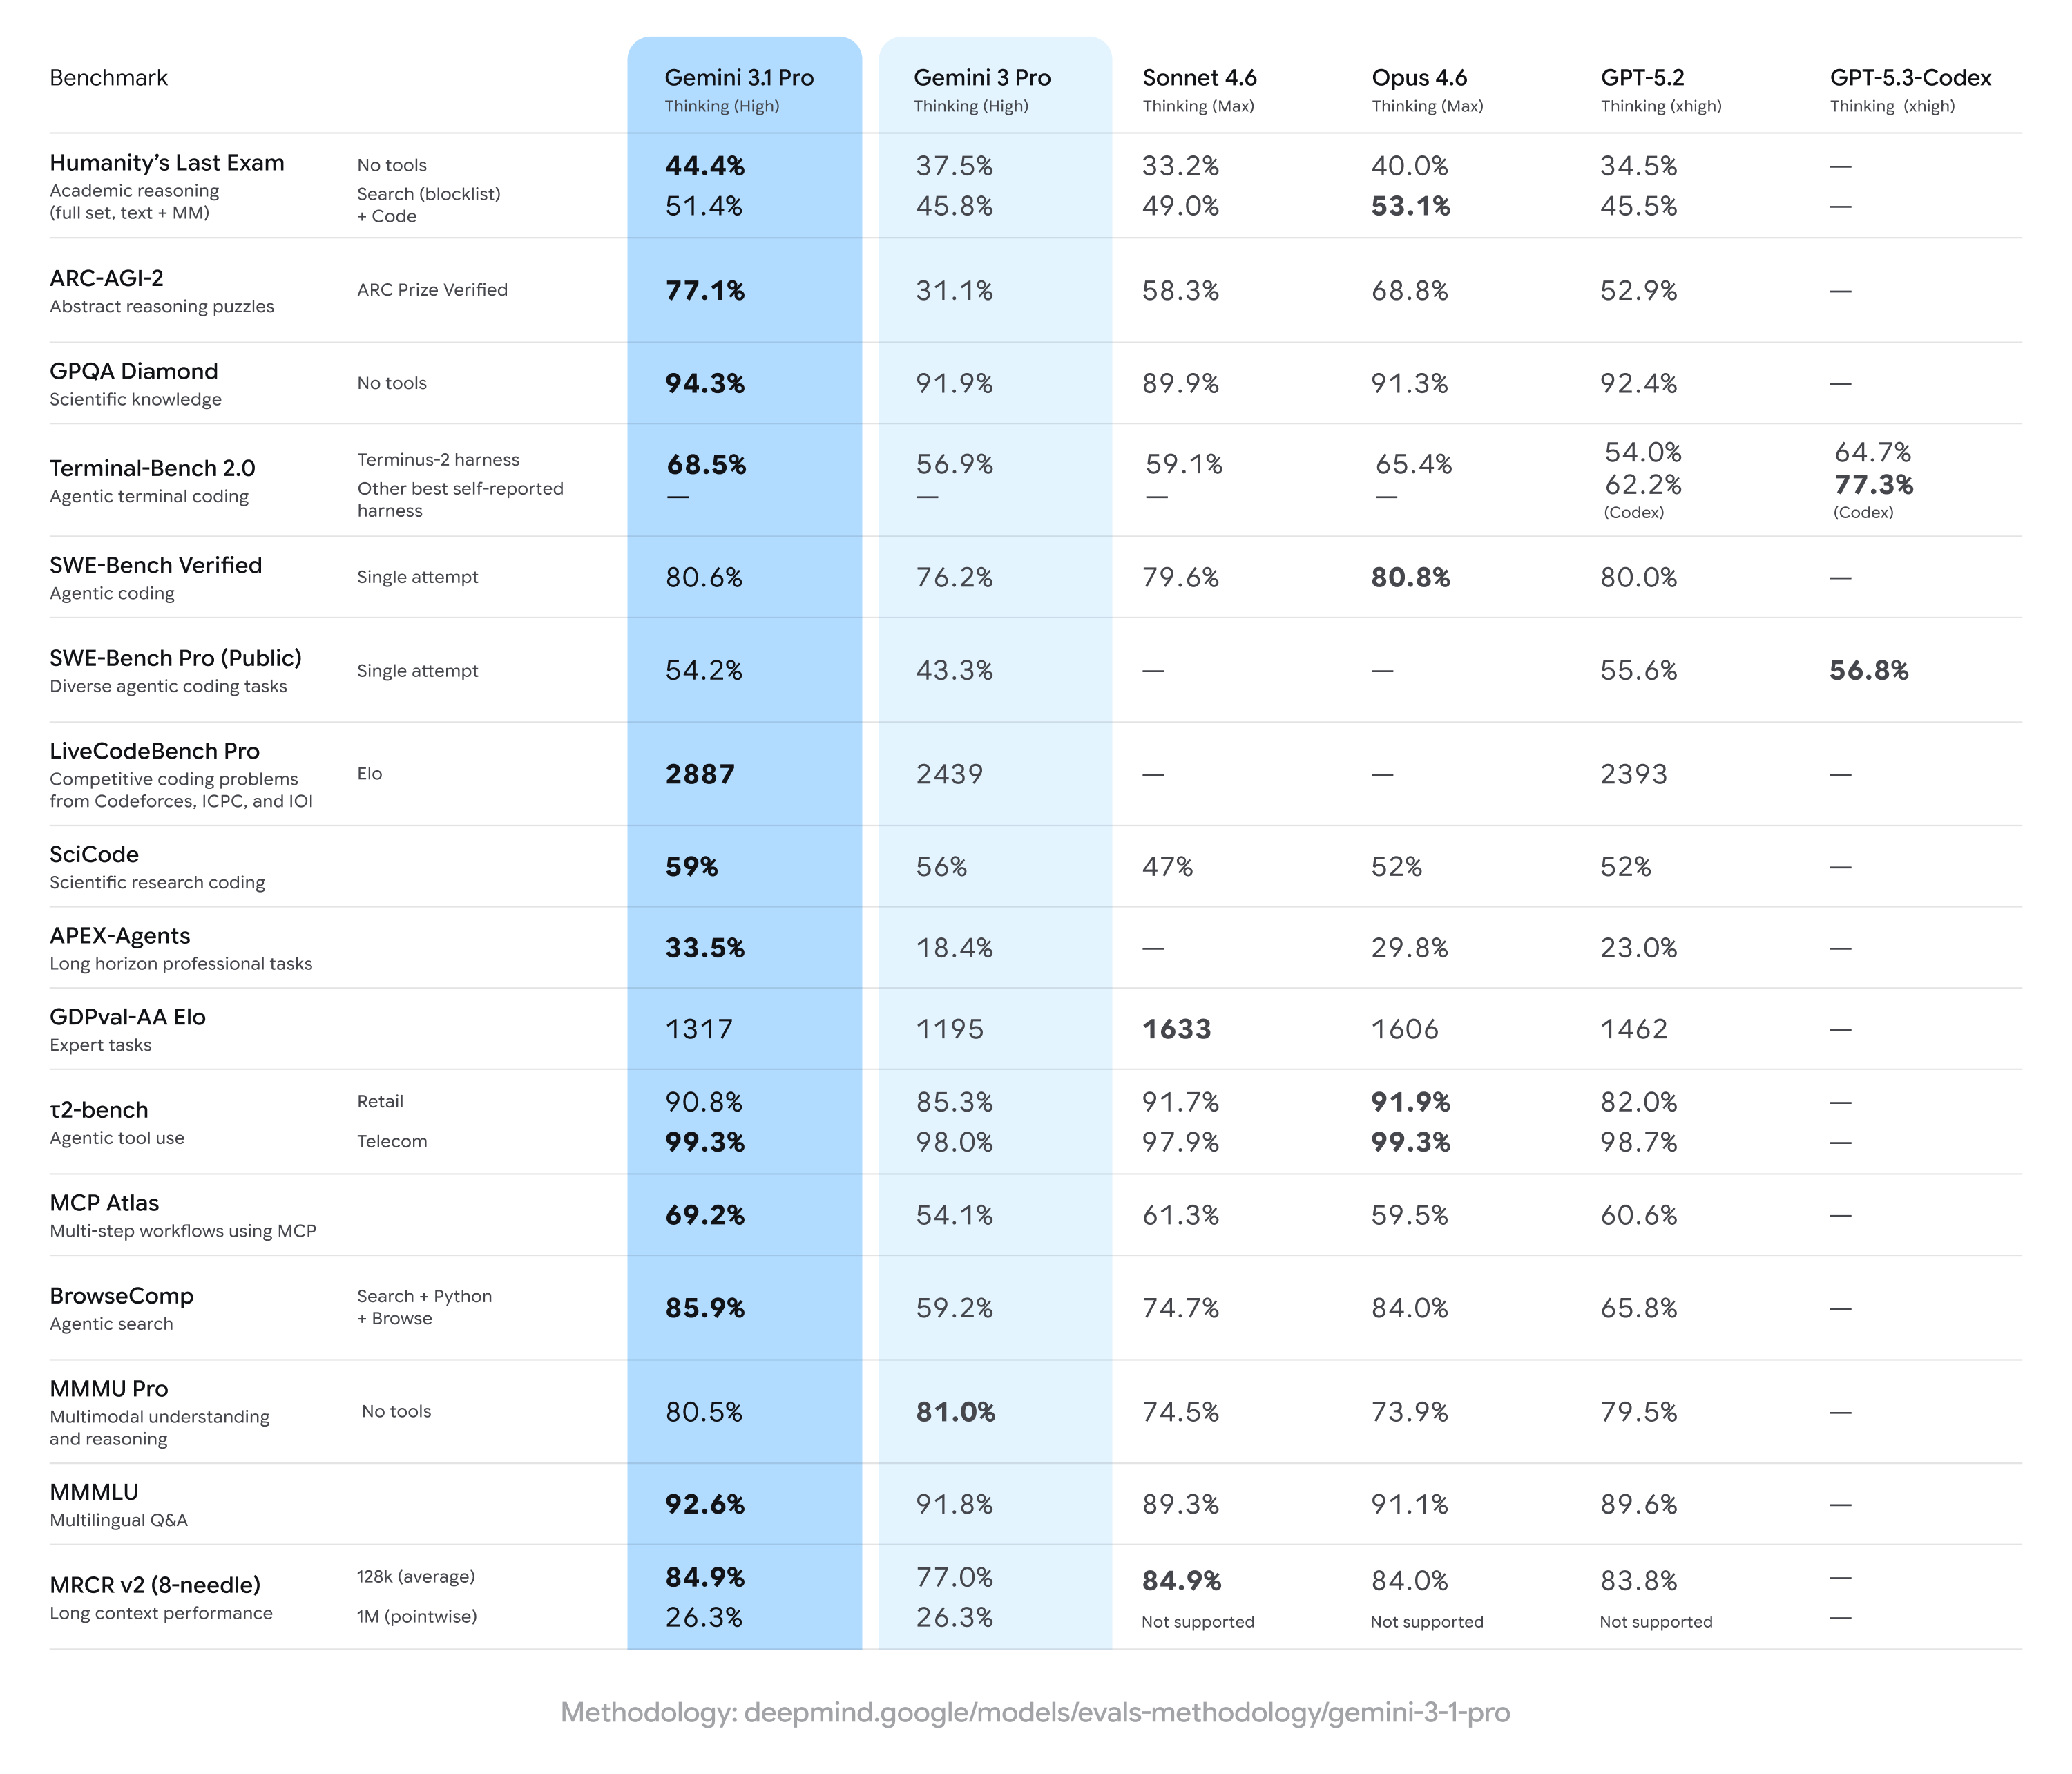
Google also calls out the model’s improvement in ARC-AGI-2, which features novel logic problems that can’t be directly trained into an AI. Gemini 3 was a bit behind on this evaluation, reaching a mere 31.1 percent versus scores in the 50s and 60s for competing models. Gemini 3.1 Pro more than doubles Google’s score, reaching a lofty 77.1 percent.
Google has often gloated when it releases new models that they’ve already hit the top of the Arena leaderboard (formerly LM Arena), but that’s not the case this time. For text, Claude Opus 4.6 edges out the new Gemini by four points at 1504. For code, Opus 4.6, Opus 4.5, and GPT 5.2 High all run ahead of Gemini 3.1 Pro by a bit more. It’s worth noting, however, that the Arena leaderboard is run on vibes. Users vote on the outputs they like best, which can reward outputs that look correct regardless of whether they are.




