ai agent benchmark
Ai agent benchmark explained — what it is, how it works and what it costs. Below are 23 articles about ai agent benchmark on CheapToken News. This is one of the main topics we track on CheapToken News.

Xin Zhiyuan reports Just moments ago, Claude Fable 5.2 and Claude Mythos 5.2 made a stunning debut! In benchmark tests, it surpassed nearly every model (basically, all of them surpassed Opus 5.5!), leading across the board in intelligent coding, scientific research, cybersecurity, and computer use. These two titans have become the “super scientist” and “chief engineer” capable of leading cutting-edge scientific research and commanding thousands of AI agent
Accelerating the Evolution of Urban Intelligent Computing Centers in Eastern China Toward E-AIDC Recently, Damo Technology and Shanghai Pudong Environmental Protection Energy Development Co., Ltd. (hereinafter referred to as “Pudong Environmental Protection Energy”) officially signed a strategic cooperation agreement. The two parties will make in-depth deployments across four key areas: data center energy-efficiency optimization and intelligent management
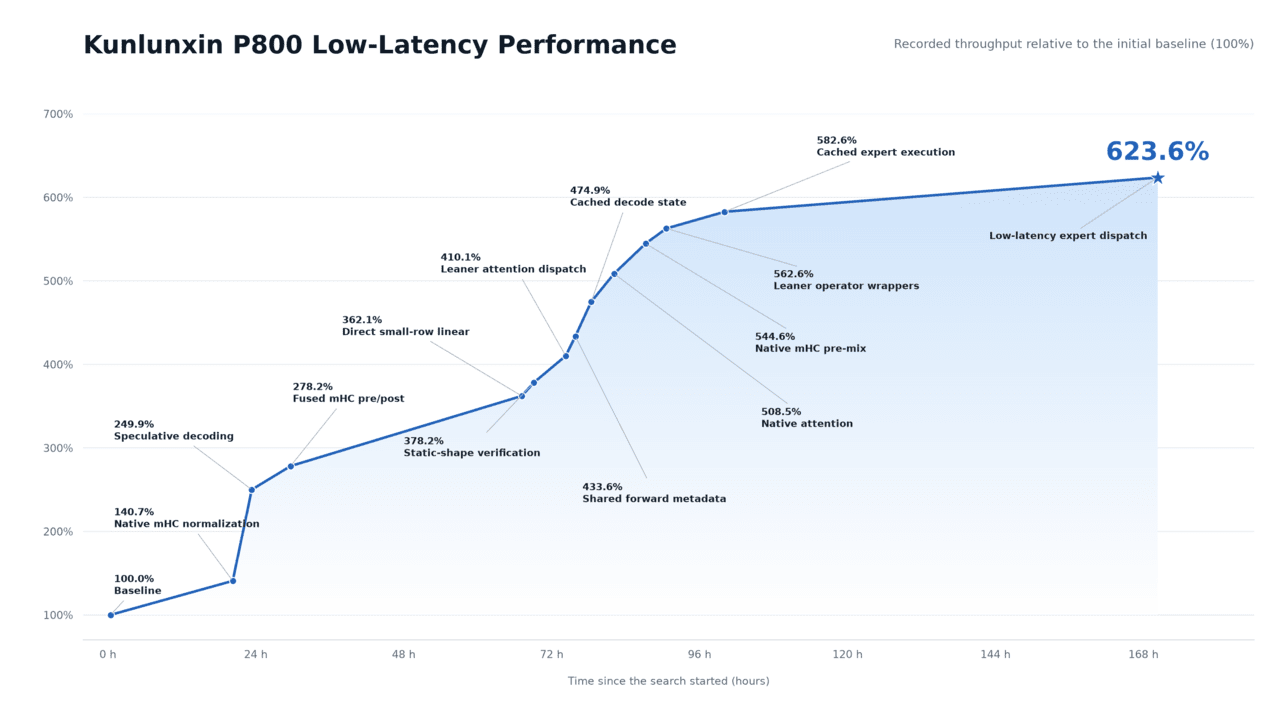
(Photo=Baidu) Chinese Baidu unveiled an automated research system for AI development in which AI independently determines research directions and repeats experiments. Following its breakthrough of existing AI training benchmark records, the company demonstrated technological progress toward recursive self-improvement (RSI), while increasing the inference speed of its own model under development by more than sixfold in certain environments. Baidu announced

For example, on the Disrupt Stage, we still have stellar speakers like A-list actor Mark Wahlberg, Replit’s CEO Amjad Masad, all five Benchmark partners in a rare joint appearance, Amazon’s Panos Panay, Bluesky’s CEO and COO Toni Schneider and Rose Wang … the list goes on. Plus, there are two flagship AI Stages, which will include OpenAI’s Head of Enterprise Product Alexander Embiricos, who will talk about the launch of the company’s Dots agents, along wit
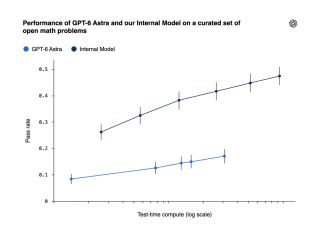
OpenAI researcher allegedly pressured mathematician to drop Anthropic co-author from math breakthrough paper Matthias Bastian View the LinkedIn Profile of Matthias Bastian Sep 8, 2026 Nano Banana Pro prompted by THE DECODER Key Points Mathematician Tristan Buckmaster says OpenAI pressured him after he and Levent Alpöge made progress on the Navier-Stokes equations using AI models. OpenAI claimed an internal model had produced a roughly 100-page proof follow

Masad said the decision was made for a number of different reasons, including cost. Replit announced a partnership with OpenAI in August, but there was never any indication that it was no longer partnering with Anthropic. “I think ChatGPT is better now,” Masad said, adding that the company uses an internal benchmark to help assess metrics like performance. “We publish a public benchmark as well, and consistently, Sol and Astra perform better on building vi
However, the methods behind these evaluations are complicated and still maturing, said Irene Solaiman, Hugging Face’s chief policy officer, during a discussion at TechCrunch Disrupt last week. Testing needs to come together into a more consistent science if the industry is to rely on them in the future. With that in mind, can we trust the current tests that are being released? “Trust is such a weighted term,” said Solaiman. “In terms of whether we can trus
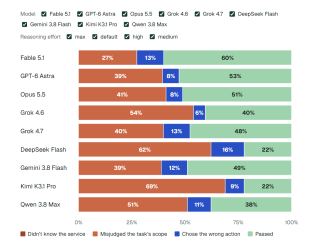
New open-source benchmark reveals reasoning as the biggest bottleneck for AI in cloud operations Maximilian Schreiner View the LinkedIn Profile of Maximilian Schreiner Nov 4, 2026 CloudOpsBench is a new open-source benchmark that measures how well AI agents handle typical DevOps tasks in the cloud, from fixing services and removing resources to restricting access rights, rolling out updates, and decommissioning projects. Version 1.0 includes 45 tasks on AW
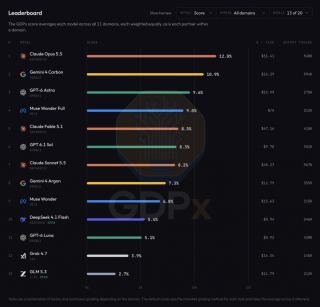
No AI agent scores above 12 percent on SemiAnalysis' new real-world work benchmark Manuel Uth Nov 5, 2026 Nano Banana Pro prompted by THE DECODER Key Points Analytics firm SemiAnalysis has released GDPx, a benchmark that tests AI agents on 206 tasks in realistic work environments and professional software over several hours. The scores are low. Claude Opus 5.5 leads the field with just 12 percent, followed by Google's significantly cheaper Gemini 4 Carbon
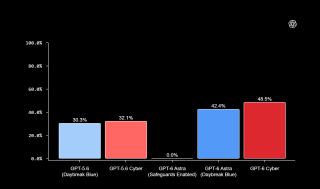
OpenAIs GPT-6 Cyber can both break into systems and propose how to fix them Matthias Bastian View the LinkedIn Profile of Matthias Bastian Nov 5, 2026 Nano Banana Pro prompted by THE DECODER Key Points OpenAI has unveiled GPT-6 Cyber, an AI model specifically trained to find security vulnerabilities, develop working exploits, and suggest patches. In targeted tests, GPT-6 Cyber found 81 previously unknown critical vulnerabilities in Firefox, which Mozilla h

@alibabacloud-saAftershock: A Disaster Simulator for Evaluating the Coordination of a Qwen Agent SocietyTutorialAIDevelopersQwenAI Hackathon0Posted at 2026-11-09TAG40@@Award-winning project in the Global AI Hackathon Series (organized by Qwen Cloud) Project Overview A disaster occurs in a virtual city. Various missions unfold on the map: a flooded residential area, a collapsed school building with disaster victims trapped inside, a hospital whose generator

Reported by Xinzhiyuan After AI agents began taking over terminals, security issues also entered the execution environment. When an agent can read files, write scripts, run commands, and continuously adjust its next action based on system feedback, a single incorrect decision may affect actual file and system state. Enabling agents to promptly identify potential risks while completing tasks has become an important issue in agent safety research. Long-horiz
Ripple-65B Preview delivers strong agentic coding results as a fully Apache 2.0 open US model Matthias Bastian View the LinkedIn Profile of Matthias Bastian Nov 6, 2026 AI chip design firm Ricursive Intelligence has trained an open language model. Ripple-65B Preview was pretrained on 12 trillion tokens and, according to the company, achieved a score of 80.52 on the TerminalBench 2.1 coding benchmark, the best result among open US models. Ripple partly uses
Nine AI agents tried autonomous research on open questions from US national labs and none passed the experts' bar Jonathan Kemper View the LinkedIn Profile of Jonathan Kemper Nov 7, 2026 Nano Banana Pro prompted by THE DECODER AI News Without the Hype – Curated by Humans Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section. Sub
AI auditors catch most agent misbehavior but flood reviewers with false alarms, new study finds Manuel Uth Nov 7, 2026 Nano Banana Pro prompted by THE DECODER AI News Without the Hype – Curated by Humans Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section. Subscribe now { "@context": "https://schema.org", "@type": "NewsArticle
AI coding agents still need human cleanup on nearly three out of four tasks in a real-world test Jonathan Kemper View the LinkedIn Profile of Jonathan Kemper Nov 8, 2026 ChatGPT-5.6 prompted by THE DECODER AI News Without the Hype – Curated by Humans Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section. Subscribe now { "@contex
Called Box Content Retrieval, the new feature allows agents to answer queries far more effectively by relying on the embedded metadata created by Nemotron. Box says the upshot for users is faster, more accurate, and less expensive queries. Nvidia’s VP of generative AI software, Kari Briski, told TechCrunch that she expects queries to be answered four times faster, with 20% fewer errors and 90% fewer tokens used. The system will be available to all of Box’s
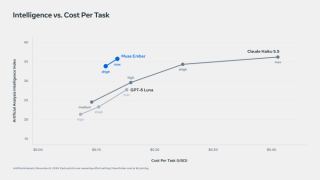
Meta particularly emphasized Ember’s cost-per-task, using Artificial Analysis’s composite benchmark score to show Ember as cheaper and smarter than competitors like Anthropic’s Haiku and OpenAI’s Luna. Image Credits:Meta Superintelligence Labs At 10 cents per million input tokens, Ember is significantly cheaper than frontier competitors like Haiku and Luna. Not only that, it’s cost-competitive with open source competitors like DeepSeek V4.1 Flash and GLM 5

Why a new report on Anthropic automating AI development is alarming researchersAI is dramatically speeding up Anthropic’s research, even as the company calls for slowing down AI development.AI is dramatically speeding up Anthropic’s research, even as the company calls for slowing down AI development.Anthropic CEO Dario Amodei. Photo: Jason Henry/Bloomberg via Getty Images is a London-based reporter at The Verge covering all things AI and a Senior Tarbell F

One codebase can run on all chips. Author | Wu Haiming Editors |Li Na, Cen Feng 01The Evolution of Grok Bot:From “Chatbox” to “Cloud Computer”Musk recently added new capabilities to Grok Bot. (Leiphone(official account: Leiphone))On October 7, he said on X that Grok Bot would integrate with top-tier third-party models such as Claude Opus 5.5, Midjourney, and Suno; and more recently, it has undergone a fundamental paradigm shift:The main bot will identify w