Tag: best llm inference cost 2026
Compare best llm inference cost 2026 — the latest prices, options and news, all in one place. Below are 5 articles about best llm inference cost 2026 on CheapToken News. It is part of our llm inference cost coverage.

The computational hurdles associated with Large Language Model (LLM) inference continue to impede their widespread deployment, particularly as prompt lengths increase. Current methods for speeding up pre-filling often struggle to maintain acceptable levels of accuracy or efficiency when applied to long-context LLMs. To address the abovementioned issue, in a new paper MInference 1.0: Accelerating Pre-filling for Long-Context LLMs via Dynamic Sparse Attentio

When language models start to "grow out of mathematics": BriLLM-MetaPred makes the first core primitive derived from AGI theory finally materialize in practiceIs the design paradigm of language models only possible by humans continuously "stacking modules and adjusting structures"? As the entire industry makes increasingly expensive incremental improvements along the line of Transformer, Professor Zhao Hai's team from Shanghai Jiao Tong University has prov

@tanakanekosuke【Overseas Tech Trends】Edge LLM・Zen 6・Local Excalidraw:Latest Dev Trends 3 SelectedPythonGitHubAITrend0Posted at 2026-11-12In recent years, "Local-first" and "Breaking Hardware Limits" have become major keywords in the developer community. This time, we will explain three practical and exciting topics selected from the latest trends gaining attention on Hacker News and GitHub: lightweight projects to run LLMs on old and low-spec devices, AMD'

Long-horizon agents are moving from "fixing a bug" to performing terminal and programming tasks for several hours continuously, but their reinforcement learning training is also exceptionally expensive: leading laboratories can scale RL across thousands of GPUs, while for most teams, a single training sample is often a complete attempt lasting three hours with hundreds of tool calls. Any mistake in any step wastes hours of GPU time. Recently, researchers W
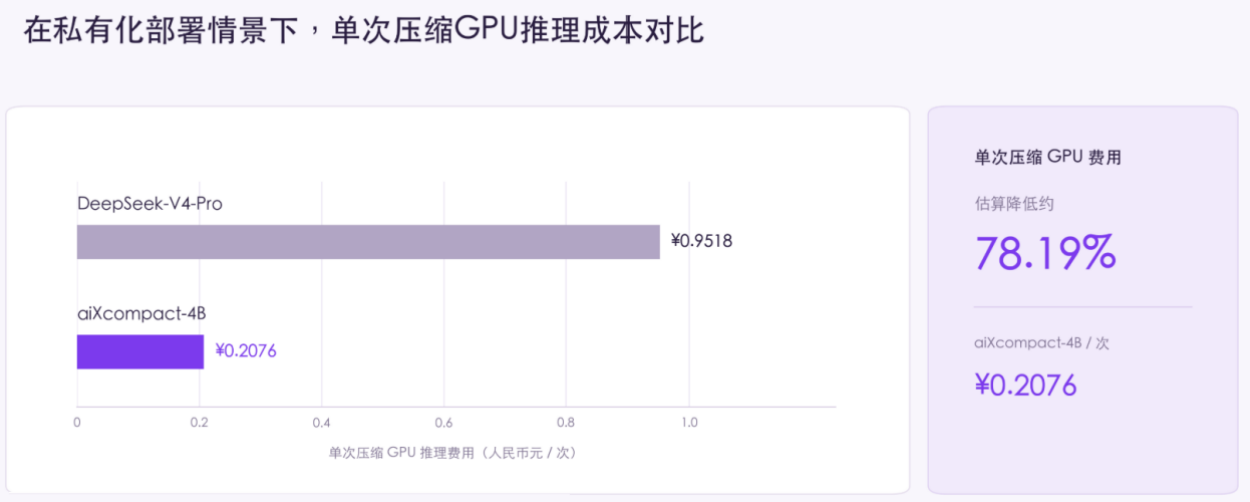
Zhidx (WeChat official account: zhidxcom) Author | Yang Jingli Editor | Li Shuiqing Zhidx reported on November 11 that today, Silicon Heart Technology (aiXcoder), an AI coding startup incubated by the Institute of Software Engineering at Peking University, open-sourcedthe context compression model aiXcompact-4B. The model is designed primarily for long-horizon, complex R&D tasks involving coding agents, has only4B parameters, andsupports private deployment