New Intelligence reports

Wenxin 5.5 Flash Preview (ERNIE 5.5 Flash Preview), officially released!
This model: fast, affordable, and open source.
Fast, really fast. It can generate over 200 tokens per second, with 280 billion parameters, and only activates 140 billion each time.
Affordable, really affordable. API pricing is 2 yuan per million tokens during peak times and 1 yuan during off-peak times, with output costing 8 yuan during peak times and 4 yuan during off-peak times, and currently offering a 50% discount.
Today, it will be available on Baidu's Intelligent Cloud Qianfan, with API direct access; the model will be open-sourced to the global community on November 25.
Wenxin 5.5 Flash Preview has been comprehensively upgraded in programming, 3D modeling, knowledge work, and content creation.
In several benchmark tests, including Terminal-Bench and AutomationBench, it has achieved competitive scores:
On Terminal-Bench 4.0, which tests real-world terminal tasks, it scored 46.5; on AutomationBench, which evaluates cross-application task handling, it scored 61.9; on SpreadsheetBench V2, which tests real Excel tasks, it scored 36.4.
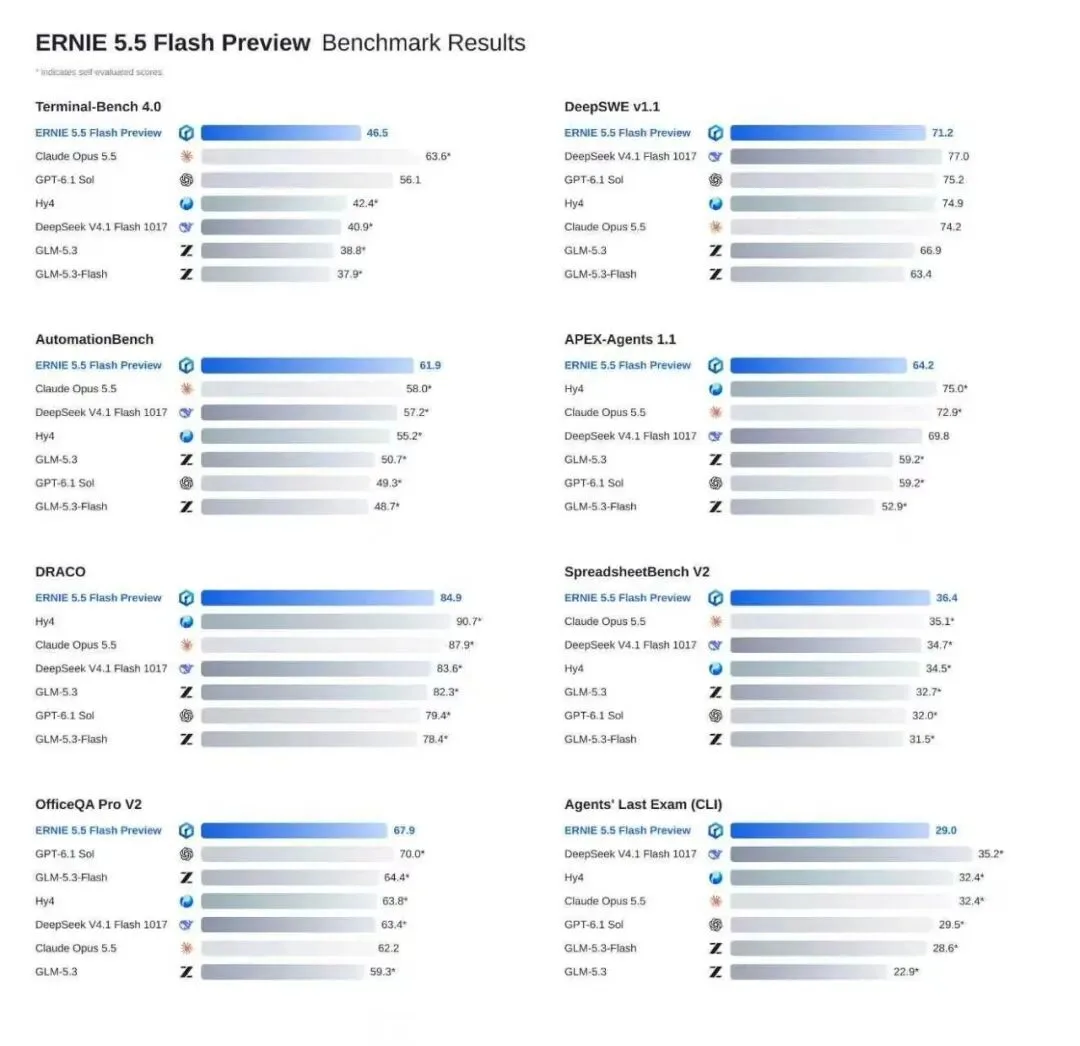
The scores marked with * are Baidu's self-test results.
There are also some ongoing projects, but don't forget its positioning: a Flash model that emphasizes speed and cost-effectiveness.
280 billion parameters, only activating 140 billion each time; 1 million token context; generating over 200 tokens per second.
With this positioning, it can compete with big names like Claude Opus 5.5 and GPT-6.1 Sol, and even take the top two spots.
When it comes to benchmark scores, I always believe only half of it. The other half, we'll see when it actually works.
Let me start with this one that really stunned me: "Cloudy Peaks Journey."
A third-person Eastern wuxia game. The misty Zhangjiajie stone peaks, an ancient temple on the cliff top. The game engine is Unreal Engine 5.8, the underlying code is C++, and it was completely made by Wenxin 5.5 Flash Preview in a 11-hour task.
11 hours isn't unusual. What's unusual is that Wenxin 5.5 Flash Preview is a pure text model, it can't see images.
The solution is very stubborn and smart: If it can't see, then measure.
For example, to check if a character is floating in the air, you don't need to look at the picture. Just write a piece of code to measure how high the character's feet are from the ground. It converted all the visual issues that came up during the trial play into code tests that can run and produce numbers, then tested, modified, and tested again in cycles, gradually refining the game until it was fully completed.
During the process, it also did a dirty job: integrating materials from several generations of Unreal Engine into the same UE 5.8 project. Different generations of engines often have incompatible formats and interfaces. Those who have made games should understand, this job, even humans would want to quit.
Honestly, what moved me about this case wasn't the visuals, but the method of working.
People who have written code know that newbies report bugs by saying "something seems off," while veterans say "the return value on line 37 is off by 0.3." The ability to turn vague feelings into verifiable numbers is a craft only masters possess.
From a pelican to a W16:
Code is its universal key.
Where does this endurance come from, being able to work continuously for 11 hours without crashing?
According to official disclosures, it trained on over 14 million "real runnable" code tasks, plus execution traces from multiple agent frameworks.
It practiced the entire process of "writing, running, checking for errors, and then modifying again." Just memorizing code isn't enough.
Plus, with a super-long context of 1 million tokens, everything it read, called, and got results from in the ten or so hours was all stored in its mind. Unreal, Unity, and Godot, these mainstream game engines, have also been specifically adapted.
How is it going? We also made a question ourselves: create a third-person 3D flying sword game, "Autumn Sword Through Clouds."
The beginning is a stone platform. The main character is wearing a green robe, with a light-colored ribbon trailing behind, and a bun on his head, standing steadily on a flying sword, not using several blocks to make up for it.
Looking ahead, there are a series of emerald-green stone peaks standing in the warm golden sea of clouds, a stone archway blocking the way halfway, and ten golden rings lined up all the way to the temple at the cliff top.
The key is that it's actually playable. After flying through the third and seventh rings, the checkpoints are automatically recorded; the number of rings, timing, and energy bar are continuously updating in the upper left corner, and there's also a small map in the lower right corner. Finally, it lands in front of the temple with red pillars and eaves, and the settlement panel pops up: all ten rings passed.
Perfect, we also let it shoot a science popularization video. The question is just one sentence: What would the world be like if the moon were only half as far from the Earth as it is now?
The finished video is over a minute long, in vertical screen format. It starts with a huge moon pressing down on the sea, and a line "The first thing to go out of control is not the sky, but the sea" pulls you in.
What surprised me was its sense of proportion. When talking about tides, it specifically added a note: it's eight times the tidal force, not necessarily eight times the tide height. It didn't wait for anyone to ask, but calculated the Roche limit itself, telling you that the moon won't be torn apart, as it's still ten times farther away from that line.
A few key numbers I checked with a calculator, and they all matched up. A Flash model did the work of an entire science popularization video team: someone looked up information, someone did calculations, someone made the graphics, and someone edited the video.
The same set of skills, just a different exam, still works.
There's a popular test in the developer community: let the model draw a pelican riding a bicycle with code. How realistic the drawing is, basically shows how good the model is.
Others submitted a single image. But the Flash Preview of Wenxin 5.5 submitted a full-length video.
"Pelican Test," an 117-second 2D animation, entirely written from scratch in Python. A white pelican pedals a bicycle, starting from the rock carvings in the Sahara Desert from 4000 years ago, passing through Han Dynasty stone carvings, Javanese shadow puppets, 8-bit pixel art, changing into 20 different art styles along the way, and finally riding into the code editor of the large model era, ending up at the "21st Pelican Release Event." In the scene of Van Gogh's "Starry Night," the swirling starscape twists in sync with its pedaling rhythm.
The background music used 22 audio recordings, from the gong drums of the Kombai people, guqin, to the Mario theme. No one else was involved in the editing: the model wrote its own editing script, aligning each scene precisely at every transition point. (Concept design by Bilibili creator @近步抱告_, with permission granted.)
The question was just to get a pelican, but it submitted a brief history of pelicans. It's a bit like cheating.
It really did practice editing videos seriously.
Officially disclosed, during training, it set up over 150,000 creation environments around scenarios such as science popularization, comedy, and creative editing, covering the entire process from idea generation, scriptwriting, storyboard creation to voice acting, producing approximately 5,300 minutes of content.
Switching to professional productivity software. Here it's testing spatial awareness: given just a text description, it needs to infer the shape, proportions, and spatial relationships on its own.
In the 3D modeling software Blender, two Wenxin intelligent agents work separately, one building an airport and the other designing an airplane.
The one building the airport goes to a map platform to find layout data, downloads supporting materials such as vegetation, vehicles, and ground service equipment; the one designing the airplane assembles the fuselage, wings, cockpit, and double-deck cabin piece by piece. Finally, both sides align the scale and camera angles, and render the final output. It's like a small outsourcing team, and they don't argue.
In the engineering design software FreeCAD, it used Python scripts to build a W16 engine, with the crankshaft turning and the pistons in the four columns of cylinders rising and falling accordingly.
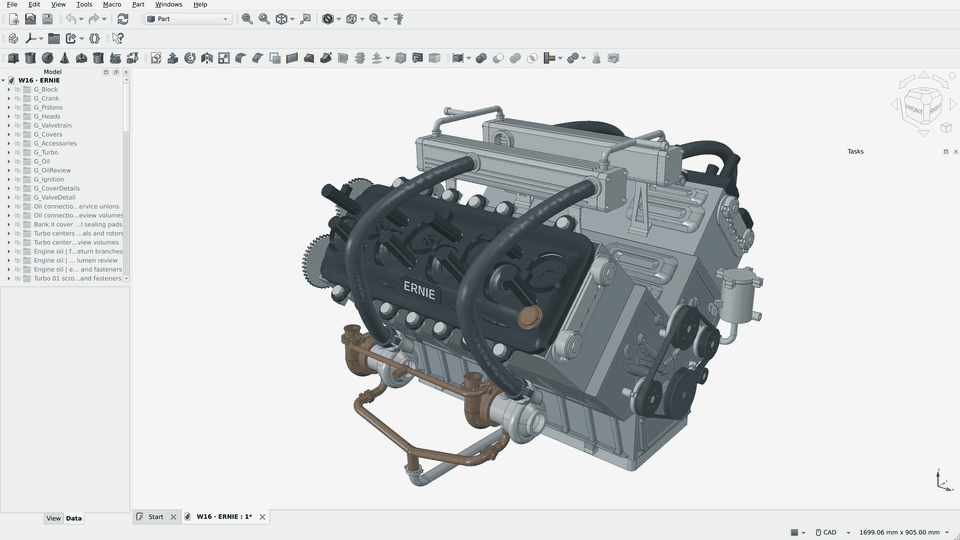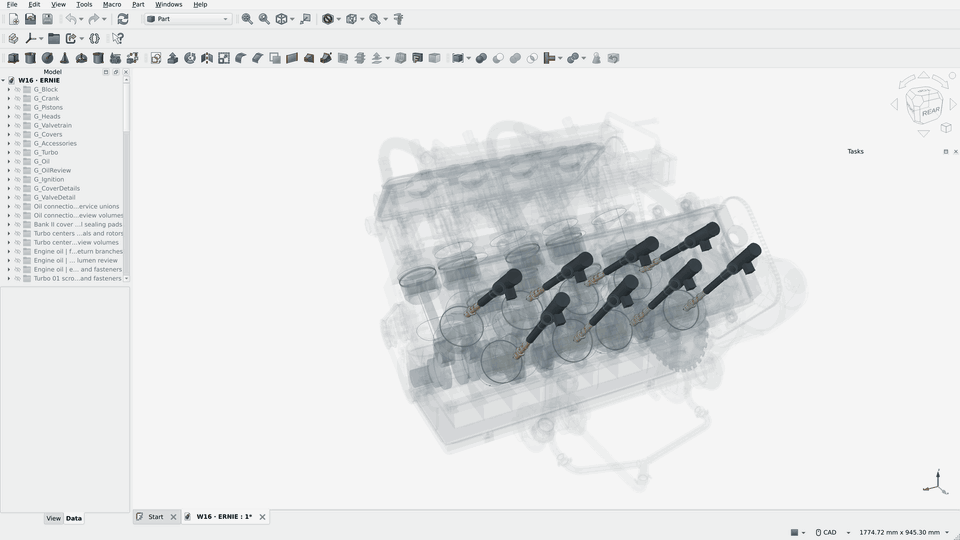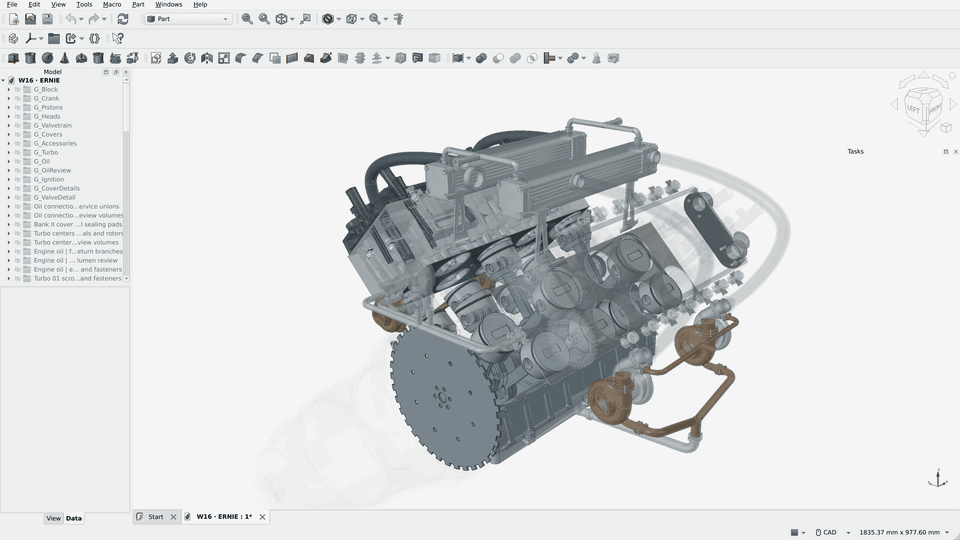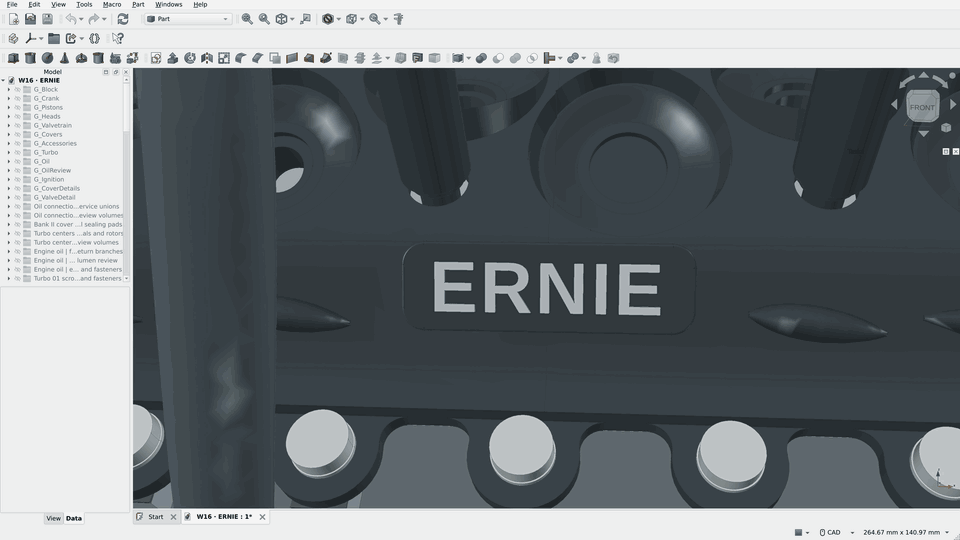
I only realized this after seeing it.
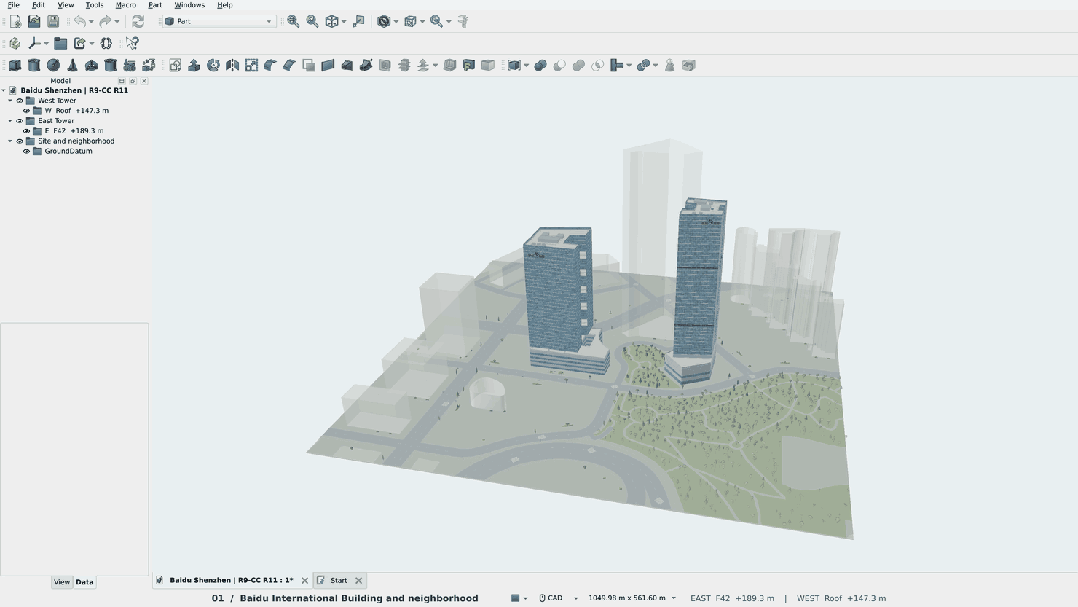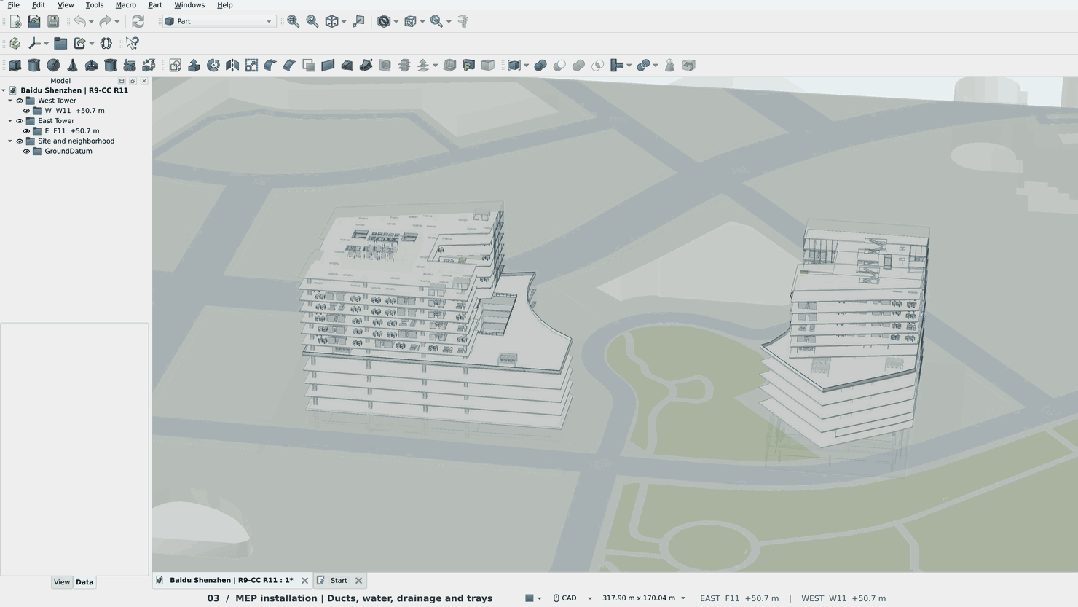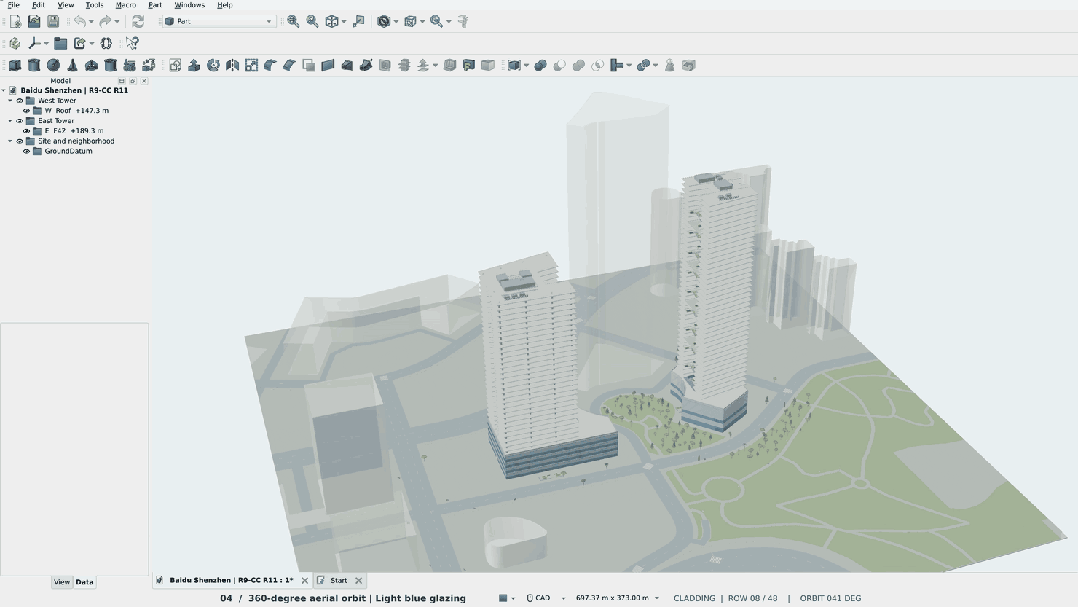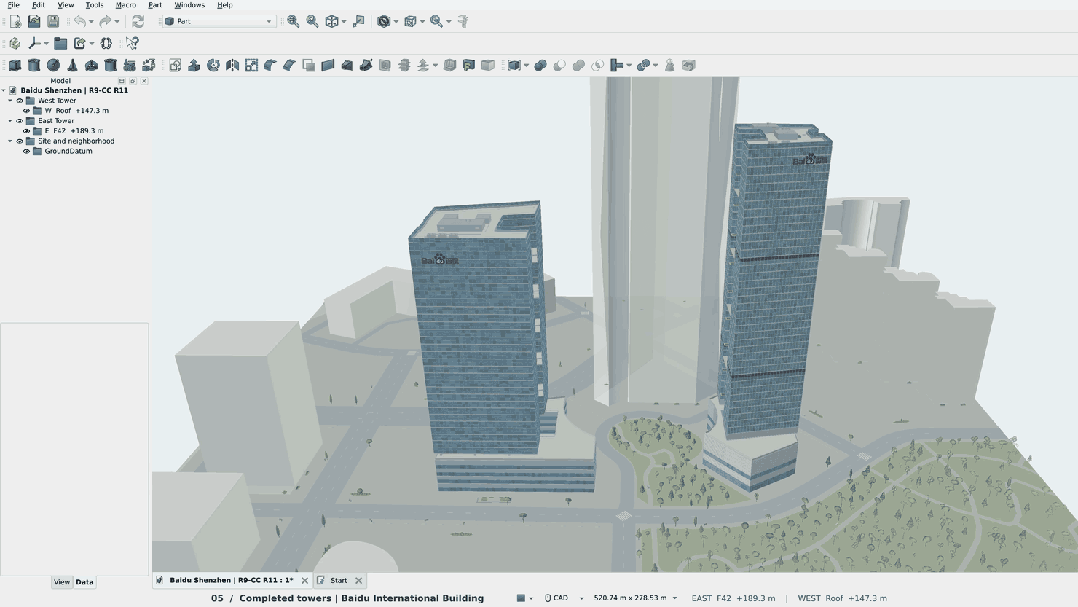
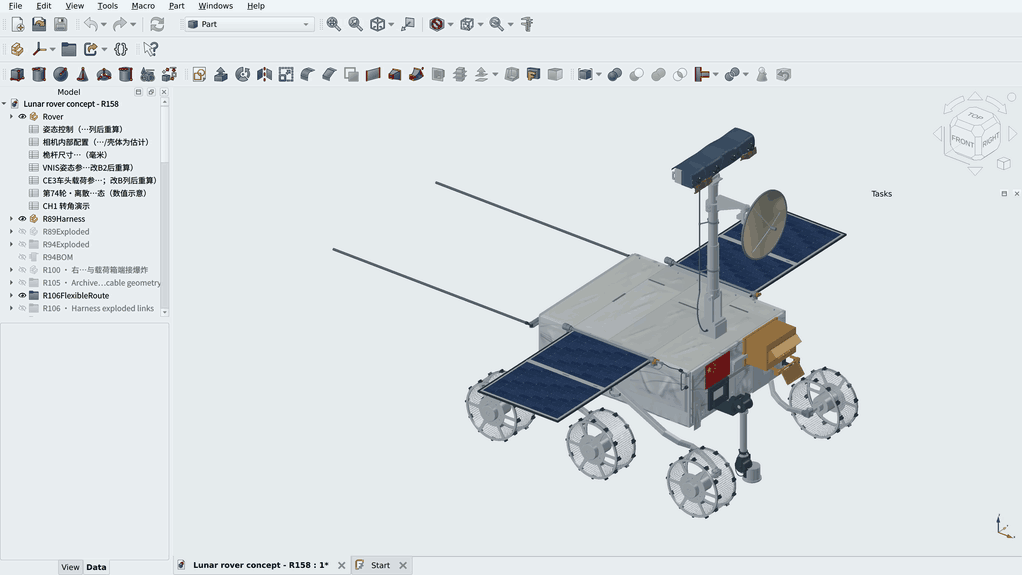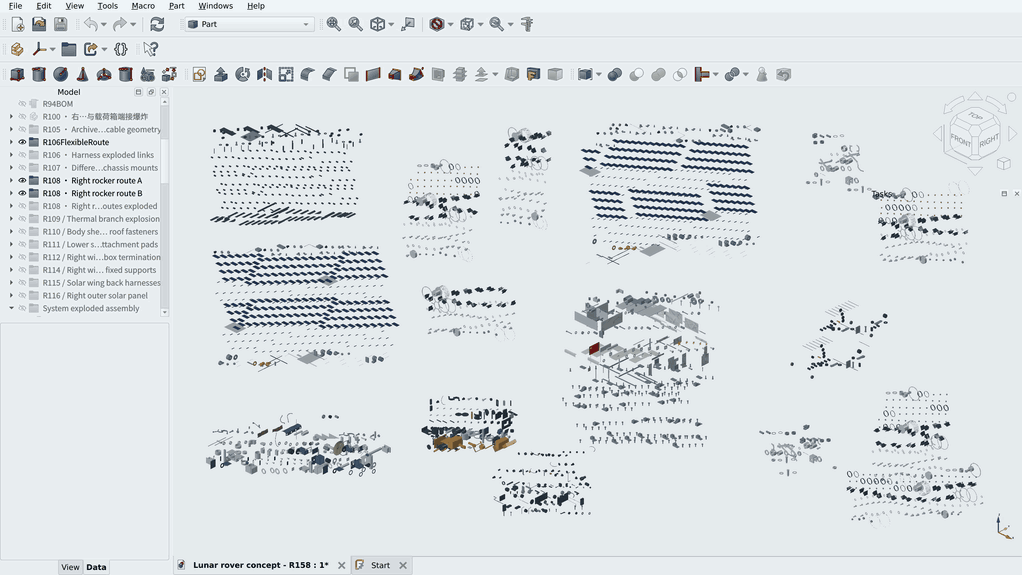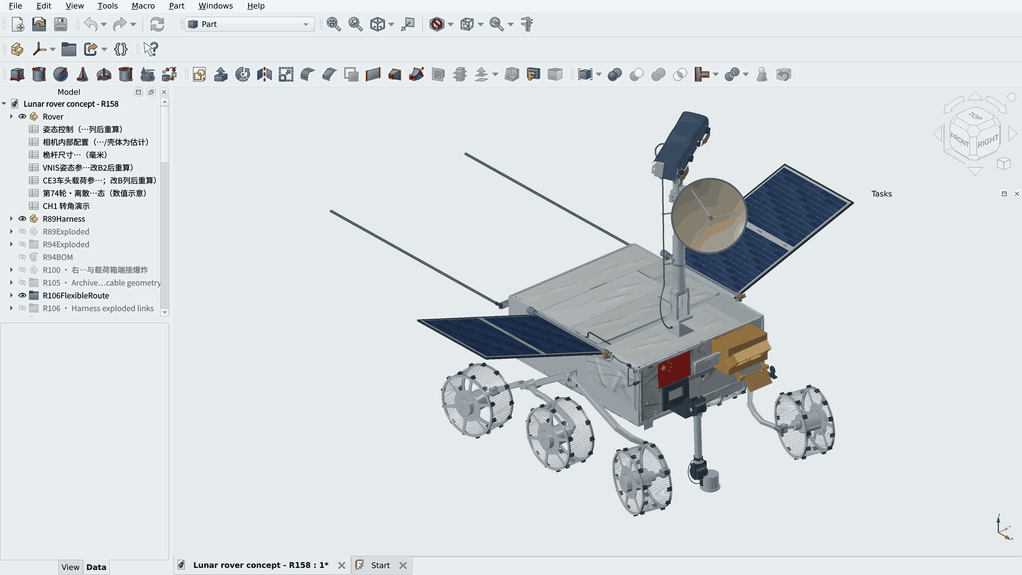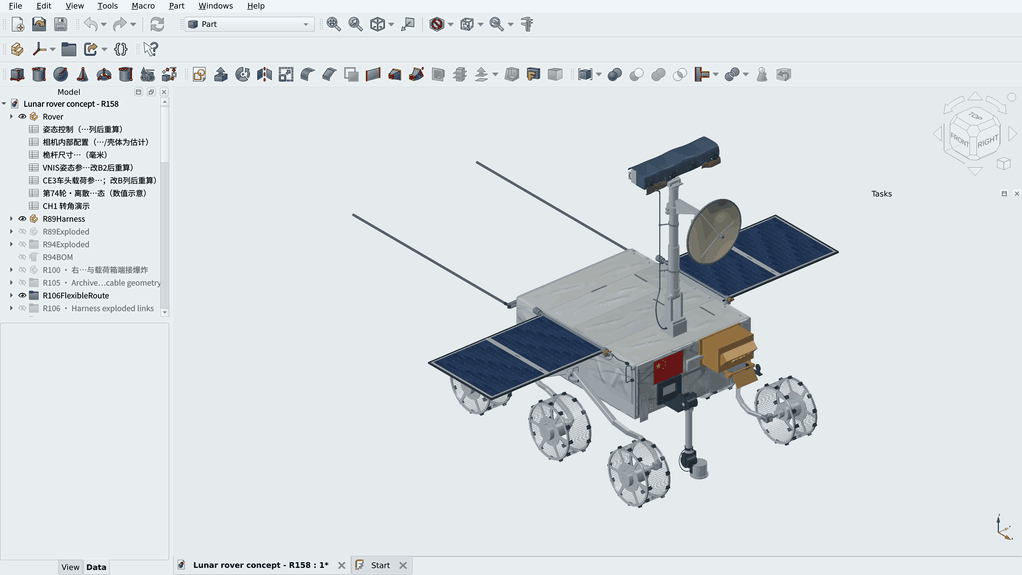
Game, animation, airplanes, engines, they seem unrelated, but in fact, they are all the same thing: writing code.
Modeling is what it does by writing scripts to direct Blender; editing is what it does by writing programs to schedule audio and video materials. Where code can reach, it can reach with its hands.
So when Baidu listed programming ability as the top highlight of this upgrade, I really respect it. This isn't just a skill, it's a universal key.
This key can even open the office door. The first two examples tested exactly this kind of task.
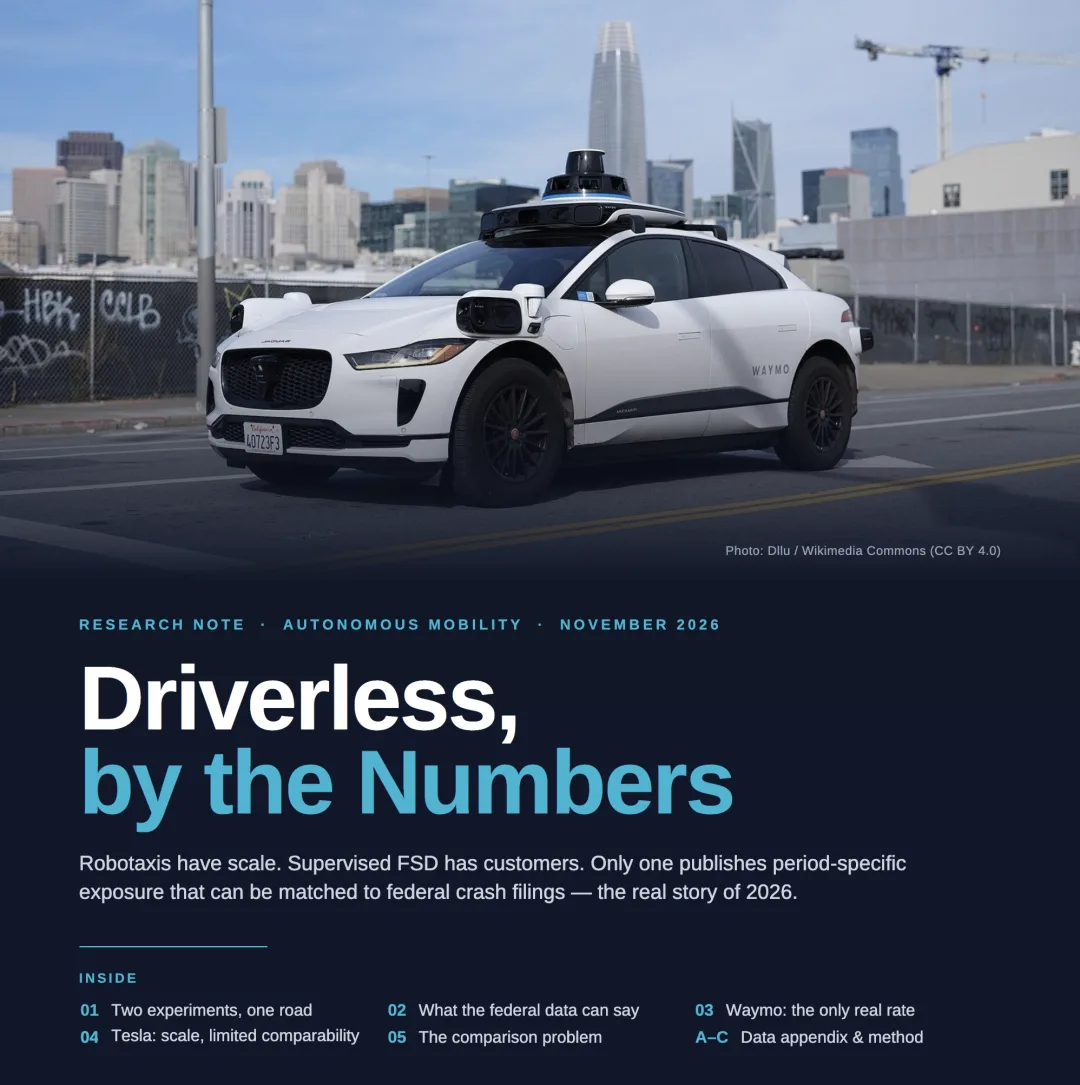
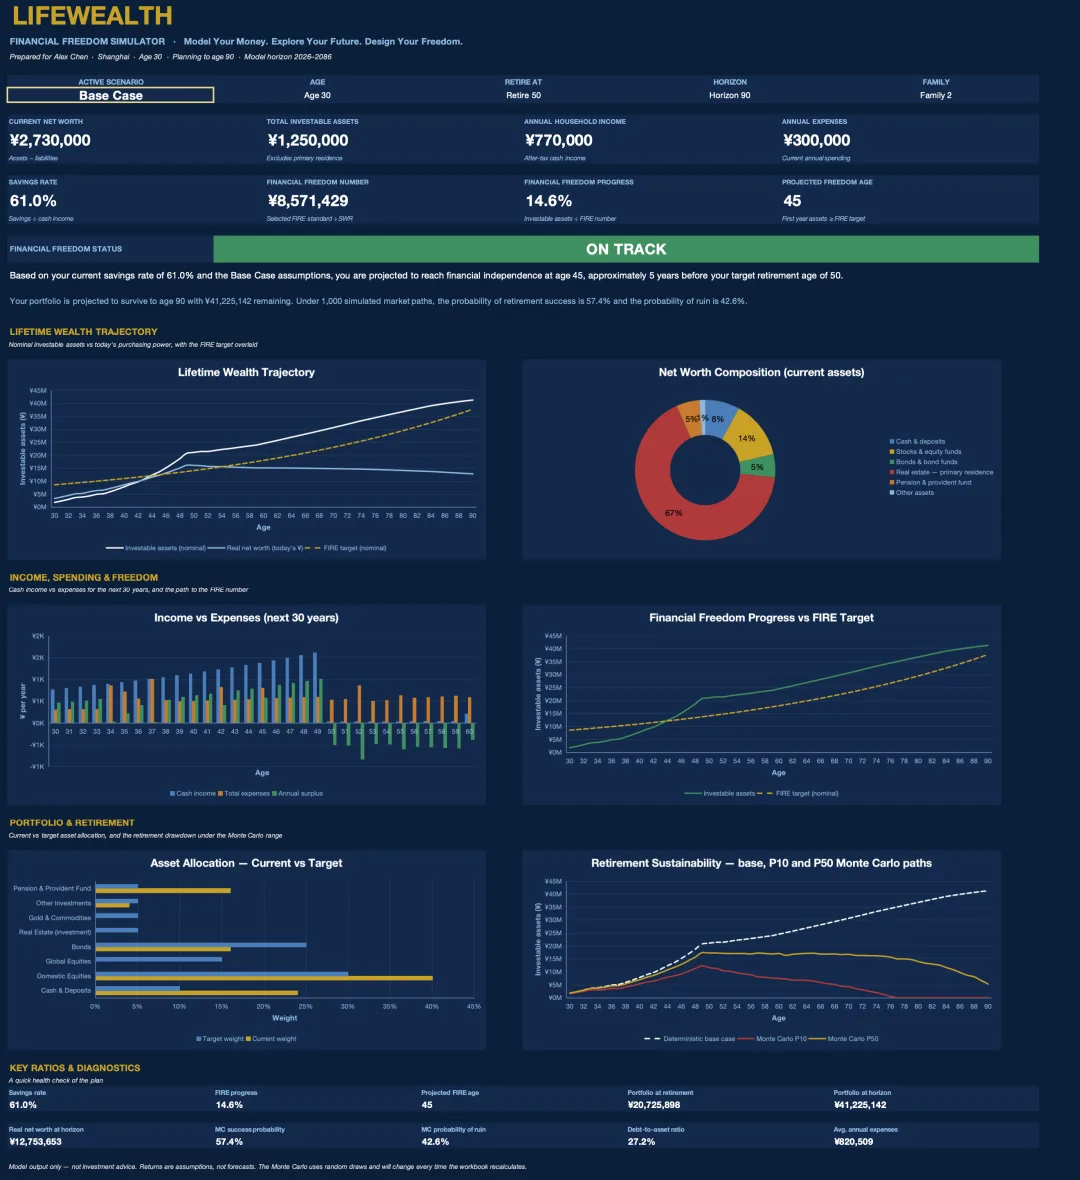
It independently wrote a 24-page self-driving car research report, analyzed 4,169 U.S. federal accident reports, compared the safety data of Waymo and Tesla's two different approaches. It also created a personal wealth planning tool, simulating 1,000 random market paths to perform predictive analysis, helping you calculate whether your retirement savings will be enough.
 |
 |
This is also something that's practiced. For knowledge-based work such as finance and law, the official has provided 300,000 workspaces and prepared 10 million reference documents, covering over 40 types of files.
It even composed its own music, generating a symphonic piece of 6 minutes and 35 seconds.
This "fast"
is partly extracted by AI itself
can do things, but doing them quickly and affordably is another matter.
The intelligent agent can perform hundreds of steps, but if each step is a bit slower and more expensive, the monthly bill could be shocking.
The architecture of Wenxin 5.5 Flash Preview is focused on "efficiency":
-
reading long texts saves memory : the model has 43 layers, of which 37 layers only read the "summary" when processing historical content, compressing every 128 tokens into one line; the remaining 6 layers process the original text word by word, but only calculate the most critical parts. It's like a project team, where most people read the meeting minutes, and only a few individuals check the original archives. Even with a million tokens input, the memory can still handle it.
-
selecting experts to prevent errors : Each layer has 512 "experts," with 10 of them being called out each time, plus one shared expert who is always on standby. The 280 billion parameters are compressed into using only 140 billion at a time. Assigning tasks also has its own logic: previously, a "dispatcher" (router) decided who would be called in, and if an expert was overlooked, they had no chance to correct their mistake, leading to persistent errors; now, multiple dispatchers rate the experts together, ensuring no one can dominate the decision-making.
-
drafting to save time : There's also a clever design called ECHO: without adding any external modules, it directly uses the model's last layer to write one word at a time, while simultaneously drafting the next few words. Once verified, it can use them directly.
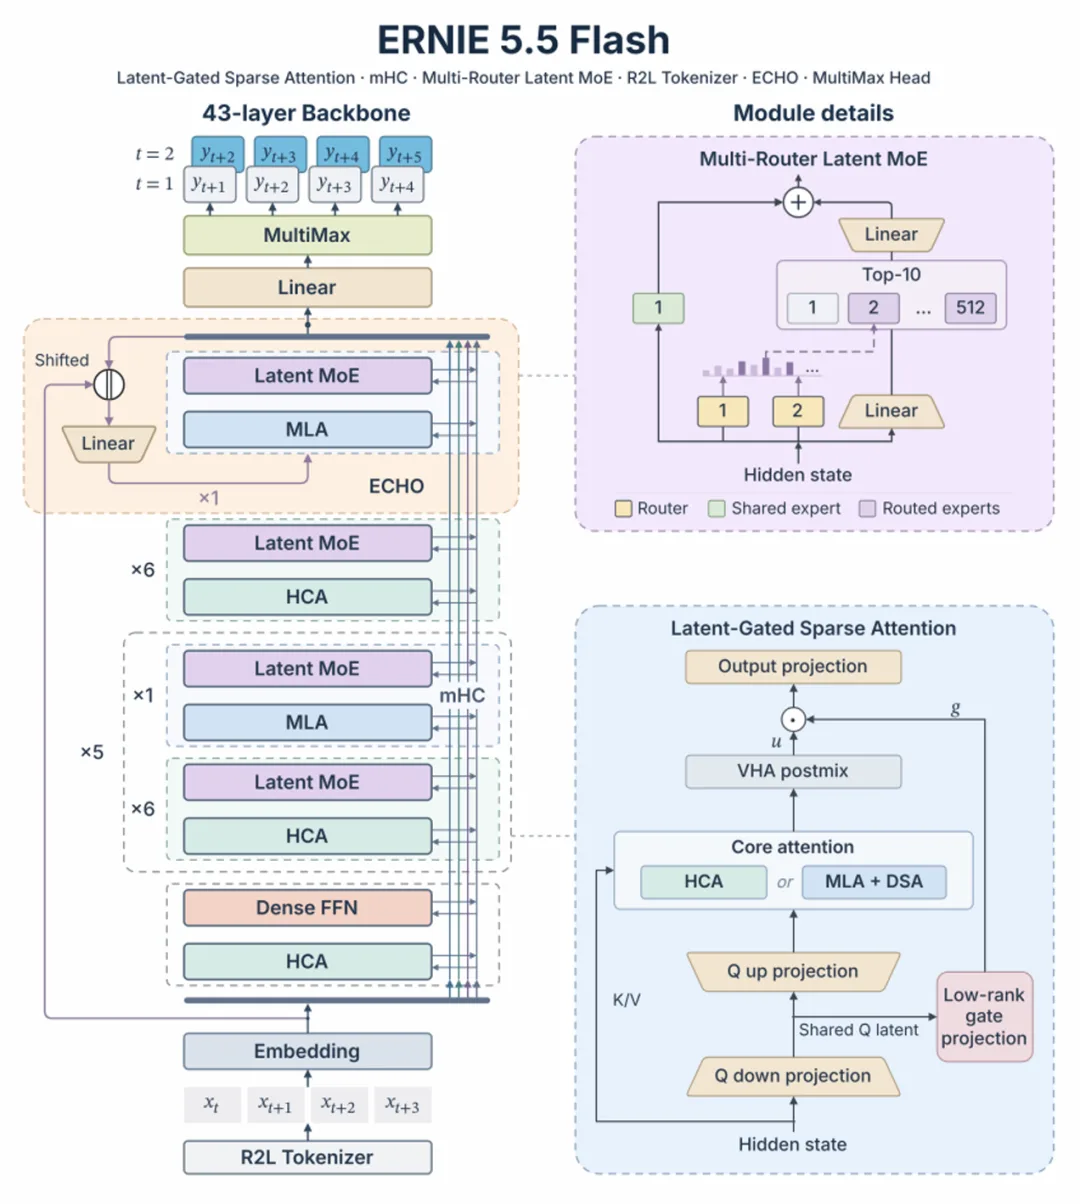
There are also a few parts with awkward names on the architecture diagram: mHC broadens the information channels between layers, MultiMax handles the final word selection step, and R2L tokenizer splits numbers into groups of three from right to left, making it easier for the model to perform calculations.
These features together enable a generation speed of over 200 tokens per second. The Flash version of Wenxin is truly worthy of its name. More interesting things are coming up. On November 9th, Baidu's Wenxin team first revealed progress in the RSI (Recursive Self-Improvement) direction: an automatic research system called ERNIE Evolve. In short, it's letting AI act as a researcher, coming up with ideas, modifying code, running experiments, and the results still have to pass independent evaluations, so there's no way to get away with cheating. The practical task it was given was to speed up the reasoning of Wenxin 5.5 Flash. The results were as follows: In the low-latency scenario on the domestic Kunlun chip P800, the generation speed was increased by 623.6% compared to the baseline. In the "deterministic reasoning" used for reinforcement learning training (where the same request generates exactly the same words and probabilities each time, at the cost of slower speed), throughput increased by 33.7%. The most impressive achievement was in the extreme decoding scenario. This scenario has already been specially optimized by human engineers, and the easy gains have already been exhausted. Remaining improvements in individual aspects are often only 0.3% to 0.5%, smaller than the measurement noise. Yet it managed to squeeze out an additional 14.9% speedup by trying seven different directions. Seven days, three consecutive releases: chasing progress is not shameful. Looking back at the calendar, Baidu's pace over these seven days was so intense it was a bit scary. On November 5th, Wenxin 5.5 Flash Base was open-sourced, which marked Baidu's first release of a model with billions of parameters in 16 months. On November 9th, they disclosed progress in the RSI automatic research. On November 11th, the Wenxin 5.5 Flash Preview was officially launched. In seven days, three consecutive releases. The next one is also scheduled: on November 25th, the weights of Wenxin 5.5 Flash Preview will be open-sourced. And tomorrow, the Baidu World 2026 conference will open in Beijing, with the theme "The Next Chapter, Intelligent Organization." They have already unveiled the new model on the eve of the conference, and the good show is probably still to come. To be honest, Over the past two years, there have been many voices around Wenxin, with both expectations and doubts. But after seeing all the developments in this week, my feeling is that this team hasn't been rushing to explain things; instead, they have been working hard, refining the architecture, focusing on efficiency, and gradually presenting their results. Even a slight increase of a few percentage points has people using AI to meticulously analyze each detail.
Catching up is not shameful. This time, Wenxin's attitude is quite open: I'm chasing, chasing seriously, and everything is here for you to test.
There's a sentence I want to send to it: No one will lift you to reach the clouds, but you can walk through the snow to the summit on your own.
Whether the summit has been reached or not, it's too early to make a conclusion. The competitors on the list are getting stronger and stronger. But these footprints in the snow are step by step, genuine and not fake. This praise is well deserved by Wenxin.
Currently, Wenxin 5.5 Flash Preview has been launched on the Qianfan platform of Baidu Smart Cloud, and developers can call it via API. The pricing is 2 yuan per million input tokens during peak hours and 1 yuan during off-peak hours, and 8 yuan per million output tokens during peak hours and 4 yuan during off-peak hours. Currently, there is a 50% discount.
Don't just listen to me. Let it play a game for you.
Experience address: https://ernie.baidu.com/web/new-chat
Editor: Solomon
Seconds to chase ASI
⭐ Like, share, and mark as read with one click.⭐
Light up the star, lock in the fastest updates from New Intelligence Yuan!