Synced Report

On August 17, programmers worldwide were forced to endure a collective outage.
After writing the code and clicking Push, the progress bar spun in place; automated tests froze, pull requests couldn't be merged, and even the AI coding assistant Copilot went offline.
The system remained stuck for more than seven hours, and that day, developers around the world waited for it to catch its breath.
Three days later, GitHub Chief Technology Officer Vlad Fedorov posted an apology:
If you were trying to ship software that day, we let you down.
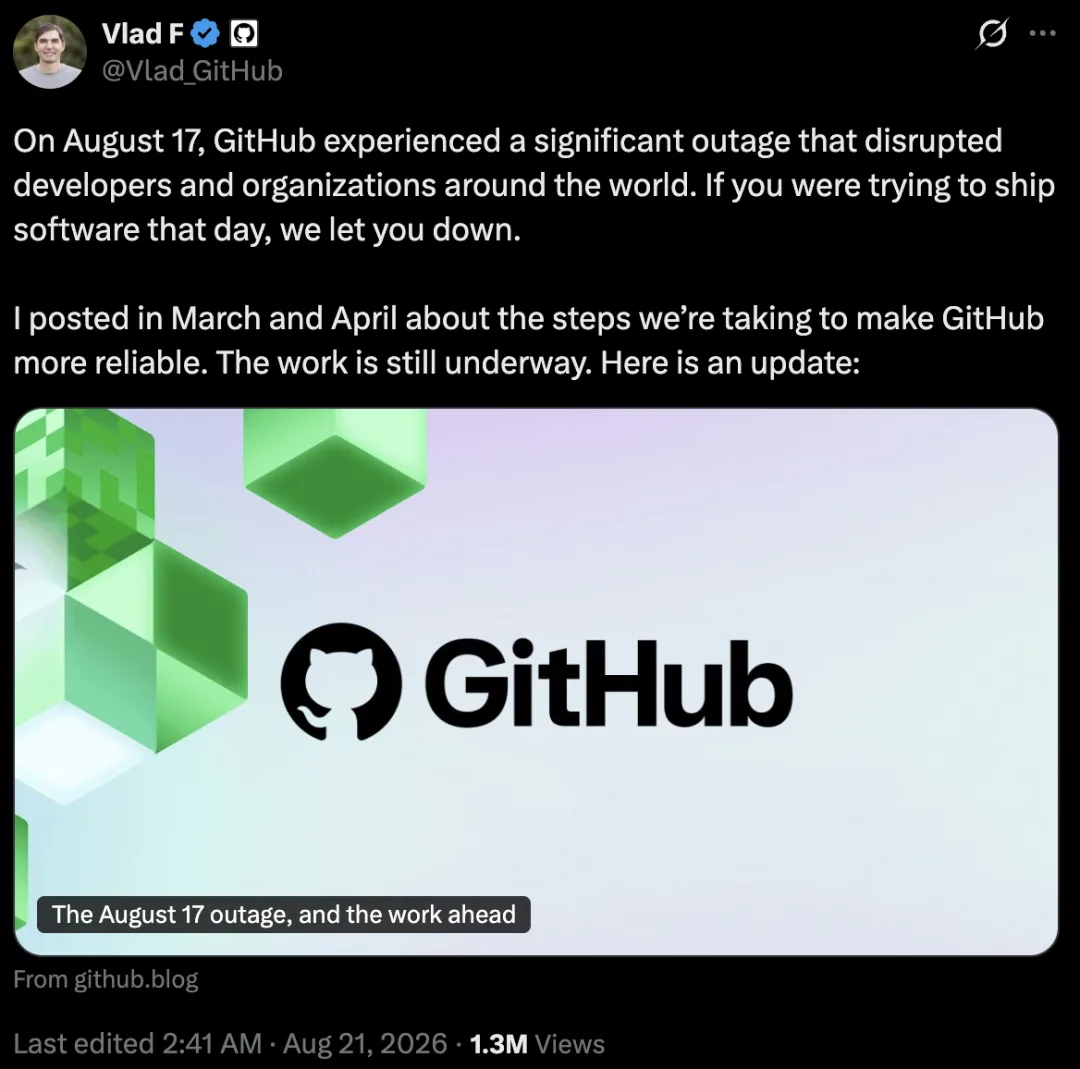
He attributed it to surging traffic: a critical component in a data center in the central United States failed to scale accordingly, and the pressure spread, causing multiple services to go down in succession.
GitHub characterized the incident as“capacity failure”,making this their second major incident in August.
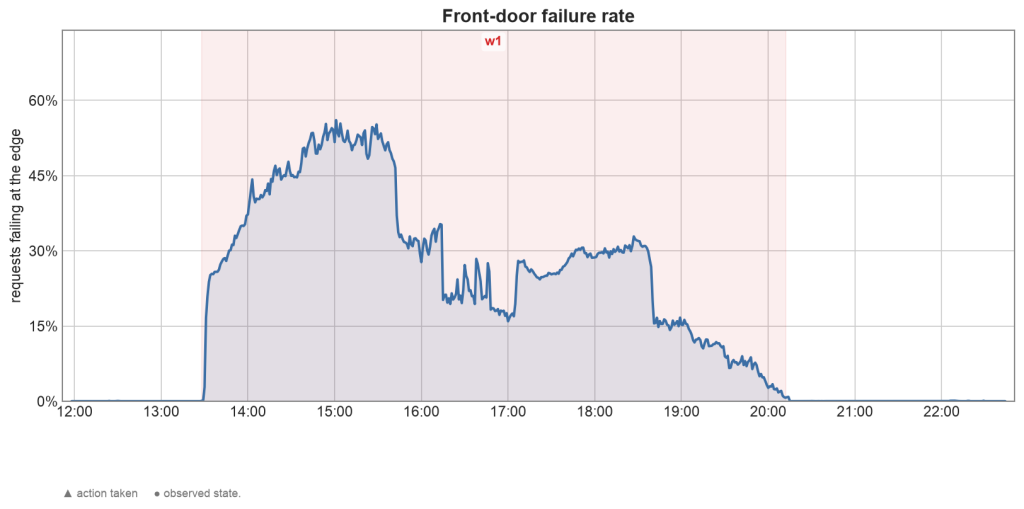
Official GitHub chart: During the August 17 outage, the request failure rate at the entry point briefly exceeded 50%.
As early as March and April, Fedorov had published details of measures to improve GitHub's reliability. He wrote in a tweet that this work was still ongoing.
So just how much had traffic on GitHub increased?
In September this year, developers and AI agents made 7.38 billion code commits on GitHub, more than five times the number a year earlier.
Just as everyone was marveling at the speed at which AI writes code, the GitHub outage brought the issue to the fore: where should all the code that had been written be stored?
The answer lies in the challenges GitHub has faced over the past six months:the bottleneck in AI code generation has shifted from being able to “write the code” to being able to “store it and merge it.”
Who Is Overloading GitHub?
First, distinguish the two actions programmers take when writing code:
Committing (commit) means saving a local version of the code;
pushing (push) means uploading that version to GitHub.
Human programmers usually save a version only after writing a stretch of code. AI agents, by contrast, are “saveaholics.”
GitHub engineers wrote on the official blog that agents save a version after virtually every step. The number of pushes also skyrocketed, rising to 4.9 times its previous level, from 690 million per month to 3.35 billion.
Already in August, a Hacker News user had raised a caveat: no matter how many commits there are, pushes are what GitHub actually has to process; this metric is inflated.
Someone immediately objected: “A single push containing 100 commits consumes more resources than one containing only 1 commit.”
In other words, commits do need to be pushed before they reach GitHub, but the more commits packed into a single push, the heavier GitHub’s processing burden.
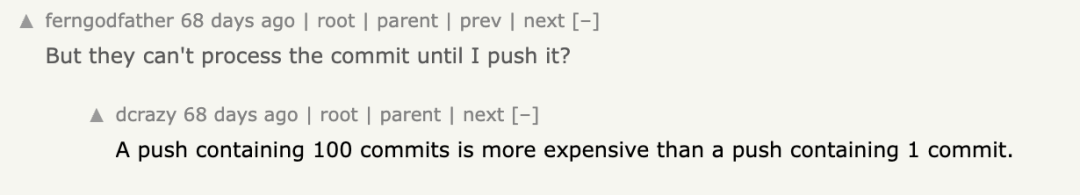
Hacker News users debated whether commit counts actually mattered.
This rebuttal struck precisely at GitHub’s pain point: agents are especially fond of saving in tiny increments. The more fragmented the saves, the higher the count and the greater the pressure.
Worse still, every push is followed by a string of “back-to-back calls”: the moment code is uploaded, automated tests and code scans swarm in, repeatedly pulling the same code.
In busy repositories, it can be pulled thousands of times per minute. It is like submitting an exam paper and having thousands of robots rush over to grade it at once.
In September, GitHub’s automated pipelines (Actions) ran 3.26 billion times, more than four times as many as a year earlier.
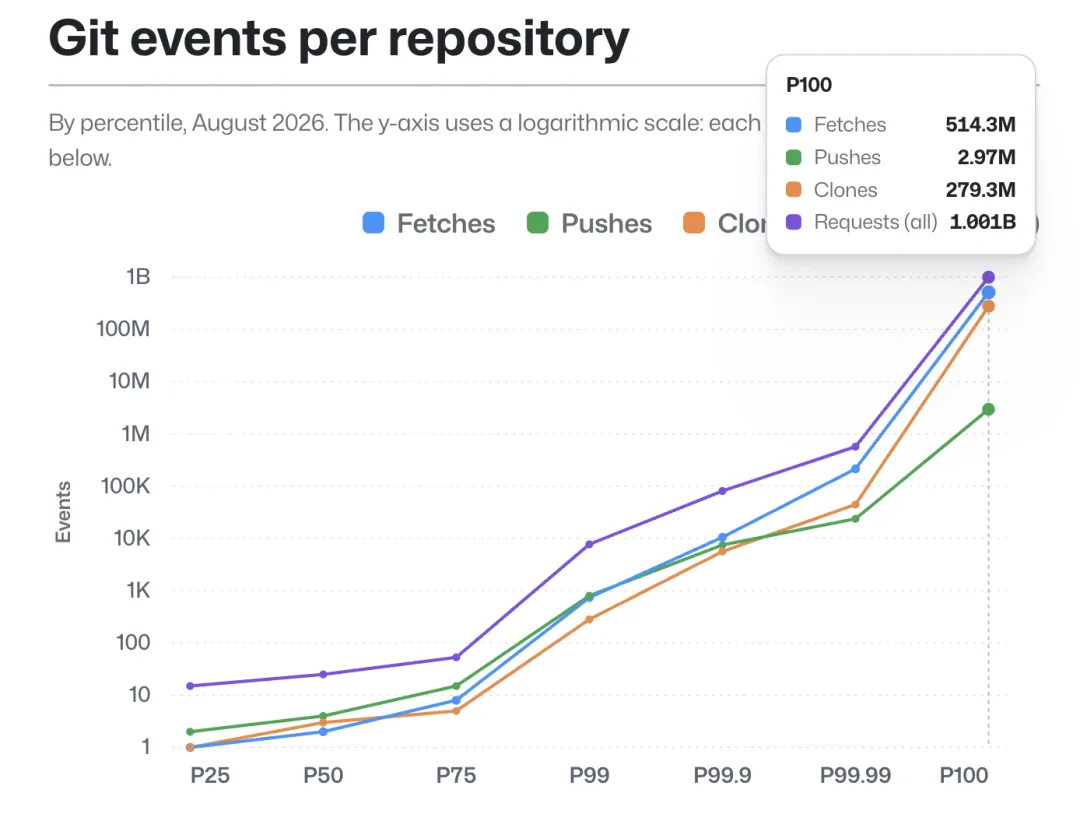
Activity levels vary dramatically across GitHub repositories: in August 2026, the busiest single repository handled about one billion requests. Each step up the vertical axis represents a tenfold increase.
According to The New Stack, GitHub attributed most of this surge to “agent demand”:
An unprecedented influx of new users has arrived. They never sleep, and their favorite hobby is pressing the save button.
Why do more backups
make archiving slower?
Once you understand the frenzy of AI agents, you will gain an even deeper appreciation of the difficulties of GitHub's legacy architecture.
To guard against data loss and distribute the load from people reading code, GitHub by default stores five complete backups of each repository, spread across five servers.
This design was very stable in the human era: losing one copy was not a concern, and it could distribute the load when more people were reading.
This legacy architecture also enabled GitHub to support 1 billion code repositories.
But in the age of AI agents, its fatal flaw was exposed.
The first bottleneck lies in "archiving."
Under the old rules, every time new code was saved, all five backups had to participate, and the final speed was determined by the slowest server.
This is like a company hiring five accountants to jointly keep one set of books: every new entry had to wait for all five to sign off before it could be entered, and it only counted once the slowest one had signed.
Moreover, only one entry could be recorded at a time. Until the previous entry was signed off, the next one had to queue. As more people came to check the books, the company would have to hire more accountants, but the more accountants there were, the longer the signing process became.
In the legacy architecture, reads and writes held each other back. The more backups GitHub added to distribute read traffic, the slower archiving became.
Yet AI agents archive every minute, and every save has to wait for the accountants to finish signing.
Even more dangerously, if too many backups failed, archiving would stop altogether. It is like too many accountants falling ill, making it impossible to keep the books.
The second bottleneck lies in "merging."
All code changes ultimately had to flow into the same main branch.
Over the course of a year, merge volume on GitHub grew to nearly four times its previous level, like thousands of cars crowding toward a single toll plaza.
How slow was the queuing, really? GitHub engineers worked through the numbers in a blog post.
When a repository's backups were split between two locations, GitHub's own data center was about 1,600 kilometers from Microsoft's cloud. A round trip took about 25 milliseconds, and each save required several round trips.
Even worse, the entire repository allowed only one write to proceed at a time. Until the previous write finished saving, the next one could only wait.
Twenty-five milliseconds is too short for even a human programmer to blink. But for AI agents, this is the hard ceiling on efficiency: how fast an agent can work depends on how quickly a single push finishes.
For years, the stability GitHub was most proud of became a bottleneck in the age of AI agents.
Start by splurging on hardware
The data center has run out of power
When faced with a surge in traffic, GitHub's first response was to add more machines.
By August, GitHub had added more than 3 million CPU cores and 120 PB of storage.
But the awkward problem still arose: the data center did not have enough power.
In his retrospective, Fedorov wrote that they had installed as much hardware as the old data centers' power supply could support.
Not only had the data centers exhausted their power, but the regional grid had also reached its limit. With every outlet full, the only way to add more machines was to move.
So GitHub began accelerating its migration to Microsoft's cloud platform, Azure: in May, Microsoft's cloud was handling only 12% of the workload; by August, that figure had risen to approximately 58%.
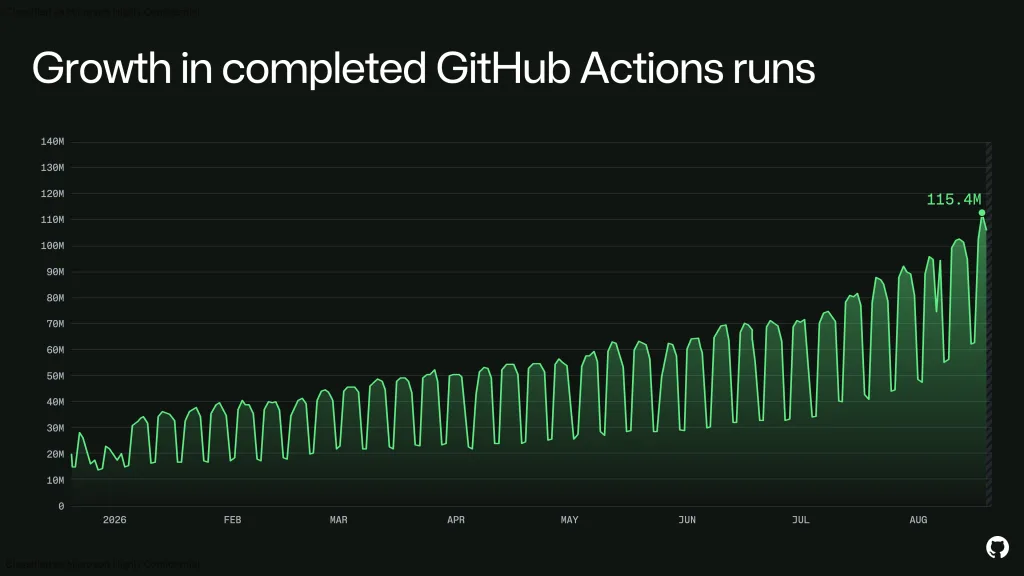
From the beginning of 2026 through August, the number of GitHub Actions runs completed per day rose from approximately 15 million–30 million to approximately 115 million.
At GitHub's annual conference on October 28, the infrastructure figures were once again refreshed:
This year, GitHub had added a cumulative 4 million CPU cores and 160 PB of storage (approximately 160 million GB), while network bandwidth had increased by 50 Tb per second.
But Microsoft executive Jay Parikh still let slip in that day's blog post that adding capacity alone was not enough; the architecture had to change as well.
Throwing money at more hardware could only buy breathing room; it could not cure the underlying architecture's chronic problems.
Swap the foundation
Separate the ledger from the counter
How do you perform surgery on the architecture? We return once again to the metaphor of the five accountants.
In the old setup, each accountant manned a counter with a complete ledger in their arms, both serving customers who came to check the accounts and looking down to record transactions.
The new setup puts the ledger in a central repository, while the counters do nothing but serve customers. Code is stored in a large repository in Microsoft Cloud; the repository handles loss prevention and backups, while the front-end servers shed the burden and do nothing but handle incoming requests.
This split brings three benefits.
First, reads and writes are separated.
No matter how many people come to read code, they will not slow down the speed of writing code. The front counters can be opened and closed as needed: when traffic arrives, open more; when it ebbs, close them; and if one breaks, replace it and another can take over immediately.
Second, redundant sign-offs have been eliminated.
In a single push, the only step that truly requires everyone’s approval is “update the branch pointer.” Moving goods into the warehouse, checking integrity, and scanning for leaked keys all proceed independently, without lining up and waiting.
Third, a major cleanup of the backend.
Previously, old data was cleaned up on the machines serving customers, competing with customer service for resources. Now it is all left to dedicated “cleaner” machines, which slowly tidy up the repository in the background.
Internal testing showed that the peak write throughput of this new architecture increased by as much as 35 times.
The real challenge is that this deeply disruptive surgery must be completed while GitHub continues to operate normally.
This is equivalent to replacing the engine on a passenger jet while it is flying at an altitude of 10,000 meters.
GitHub Goes Down Your Agents Have to Stop Too
You might think, “What does GitHub’s scaling have to do with ordinary developers?”
It matters a great deal.
Regardless of which large model you use or which agent shell you put around it, much of the code it writes still has to be pushed to GitHub.
On August 17, the day GitHub went down, Cursor released its own code-hosting platform, Origin, which was viewed as an alternative to GitHub.
But on the same day, Cursor’s status page also posted an announcement:
The GitHub outage affected some Cursor services, including automation and cloud agents, for 6 hours and 6 minutes.
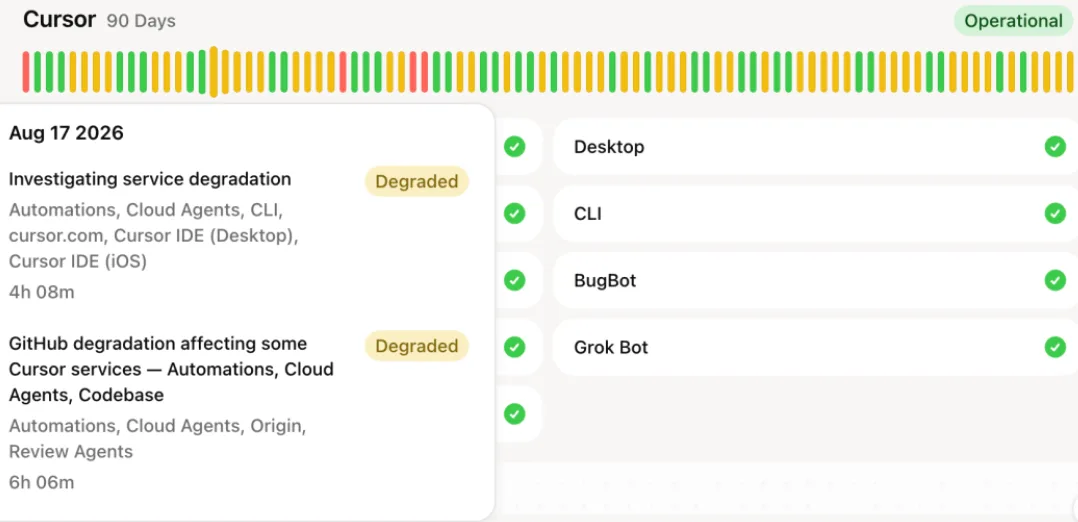
Cursor status page: On August 17, a GitHub outage affected some of its services and lasted for 6 hours and 6 minutes.
Alternatives have emerged for code hosting, but agent workflows still cannot do without GitHub.
That afternoon, a Hacker News post asking “What are the alternatives to GitHub?” climbed to 649 points. Even the home of code can let people down, and programmers began seriously looking for backup options.
Even more surreal, GitHub is packed with agents on one hand while creating even more agents on the other.
At its conference on October 28, GitHub unveiled another suite of new tools that let agents work in parallel.
As AI drives down the cost of writing code,the bottleneck will not disappear; it will simply move downstream.
First came “can it be written,” which large models solved. Now it is “can it be stored,” and GitHub is reworking its ledgers and replacing its underlying infrastructure.
Next comes “can it be merged.”
GitHub engineers themselves admit:the next hurdle is still write capacity. The old approach that brought GitHub to one billion repositories will not carry it to the next billion.
After that comes “who signs off.”
GitHub wrote a principle in a blog post: The more work agents do, the more the code’s owner must be able to review it, understand it, and make the final call. Unreviewed changes cannot enter the main branch.
On the road to ASI, this step is critical.
AI can already write code, but to make it truly deliver software, all of the infrastructure built for human typing speed will have to be rebuilt.
GitHub will not be the last one cornered.
Microsoft executive Jay Parikh also made a bold prediction:
All the software humans have written to date may amount to less than 1% of the total software produced over the next five years.
If he is even half right, then when code becomes too abundant to review, the things scarcer than CPUs will be a submit button that can always be clicked and someone willing to make the call and approve the merge.
References:
https://github.blog/news-insights/company-news/github-universe-2026-evolving-every-layer-of-the-stack/https://github.blog/engineering/building-git-infrastructure-for-agent-scale-development/
https://thenewstack.io/github-7-4b-commits-september/
https://thenextweb.com/news/github-universe-copilot-fusion-octoverse-agents
Editor: Yuanyu
Catch up on ASI in seconds
⭐Like, share, and view—all with one click⭐
Light up your star and stay tuned to Synced’s lightning-fast updates!