Pretraining: 31 billion tokens
2.2 continues the pretraining of base version 2.1: I added another approximately 19 billion tokens to its 11.8 billion, for a total of roughly 31 billion. Mixture:
Wikipedia in three languages: 23%;
CulturaX (web) in three languages: 13%;
Python code: 16%, web code: 5%;
Cosmopedia and Zyda-2: 5% each;
poetry 4%, facts 5%, translations 5%;- TAG26@@synthetic text-processing data (spelling, word analysis, CAPS): 4%;
- TAG30@@synthetic code written by DeepSeek 4 Flash: 1%;
- TAG34math: 14%.
TAG44
TAG46@@The previous model version also had step-by-step, digit-by-digit arithmetic, but the new version has more complex and varied examples. The generators cover addition and subtraction of numbers with up to 40 digits, multiplication, division with remainder, parentheses, equations, fractions, and systems. Python calculates every answer, so there are no errors in the data.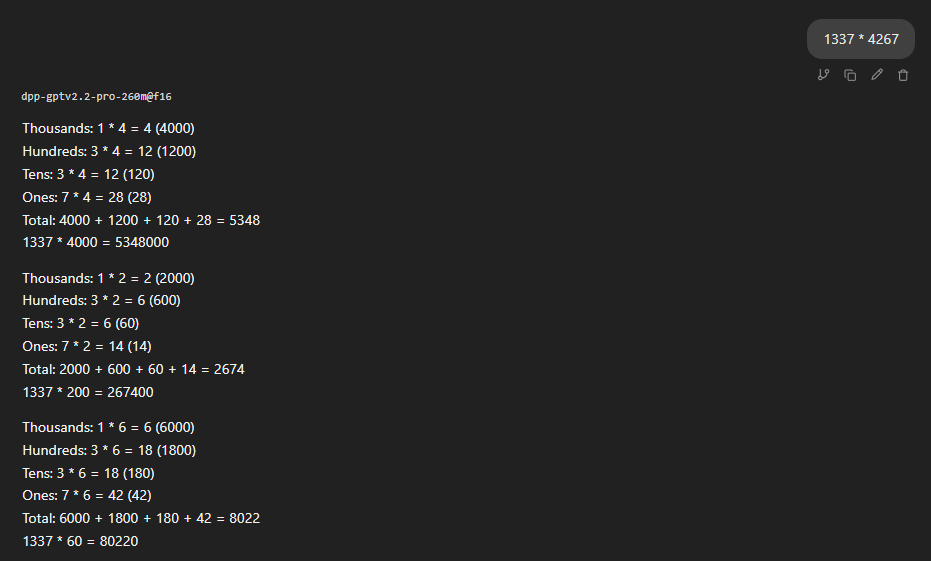 TAG49
Multiplication 1337 × 4267 digit by digit (the answer is correct)
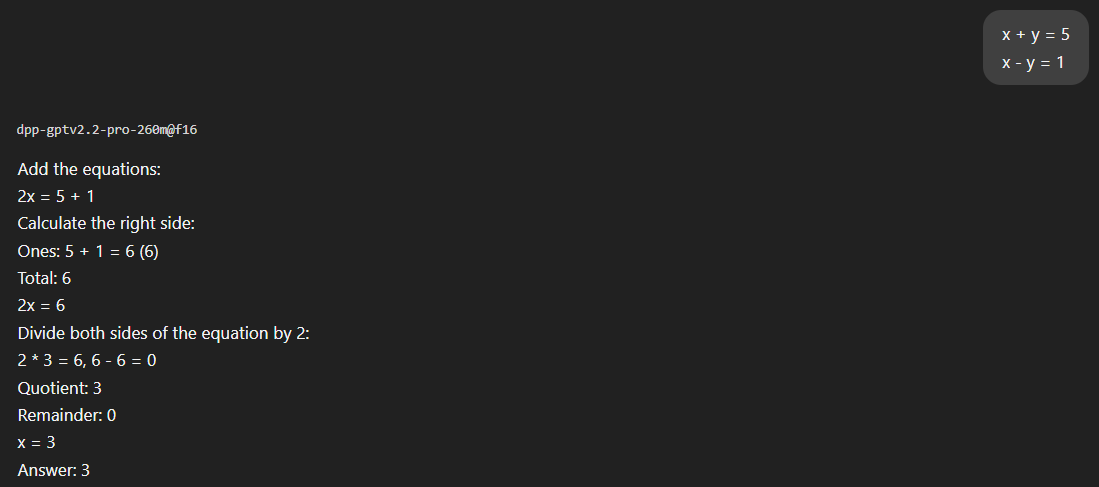 TAG53@@Solution of a simple system of equations. X was found correctly, Y was forgotten.


