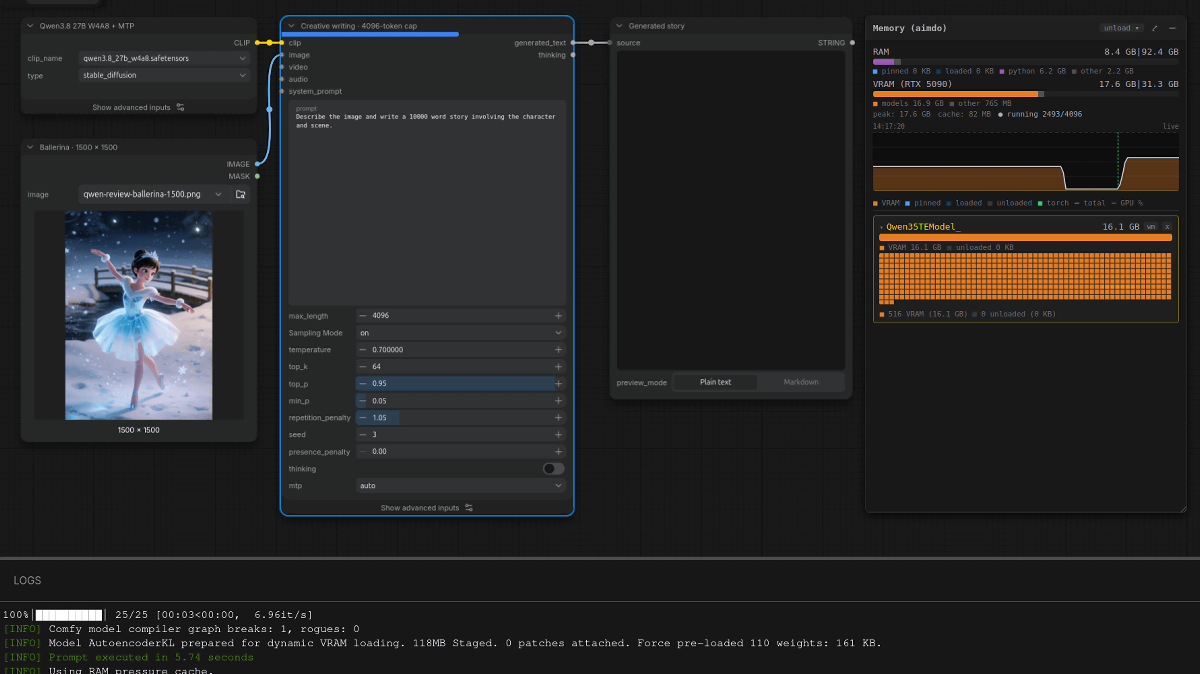
ComfyUI's main use cases are image and video generation, but it also supports text generation using LLMs or VLMs to improve prompt quality and create video stories. From version 0.40.0 to 0.45.0, ComfyUI has been optimizing text generation processes, achieving more than double the generation speed compared to previous versions.
Doubling LLM token rates in ComfyUI - by rattus128
https://blog.comfy.org/p/doubling-llm-token-rates-in-comfyui
While the performance of image and video generation AI has improved, allowing for more detailed control over generated content through prompts, issues such as "it's tedious to manually write detailed instructions" and "difficulty in writing prompts that align with the prompt structures each AI excels at" have also emerged. To address these issues, ComfyUI's official workflows and community workflows have increasingly adopted mechanisms where "input text or images are parsed by LLMs or VLMs, and appropriate prompt formats are generated before passing them to image or video generation AI." As a result, ComfyUI is now also required to improve the speed of text generation in addition to image and video generation.
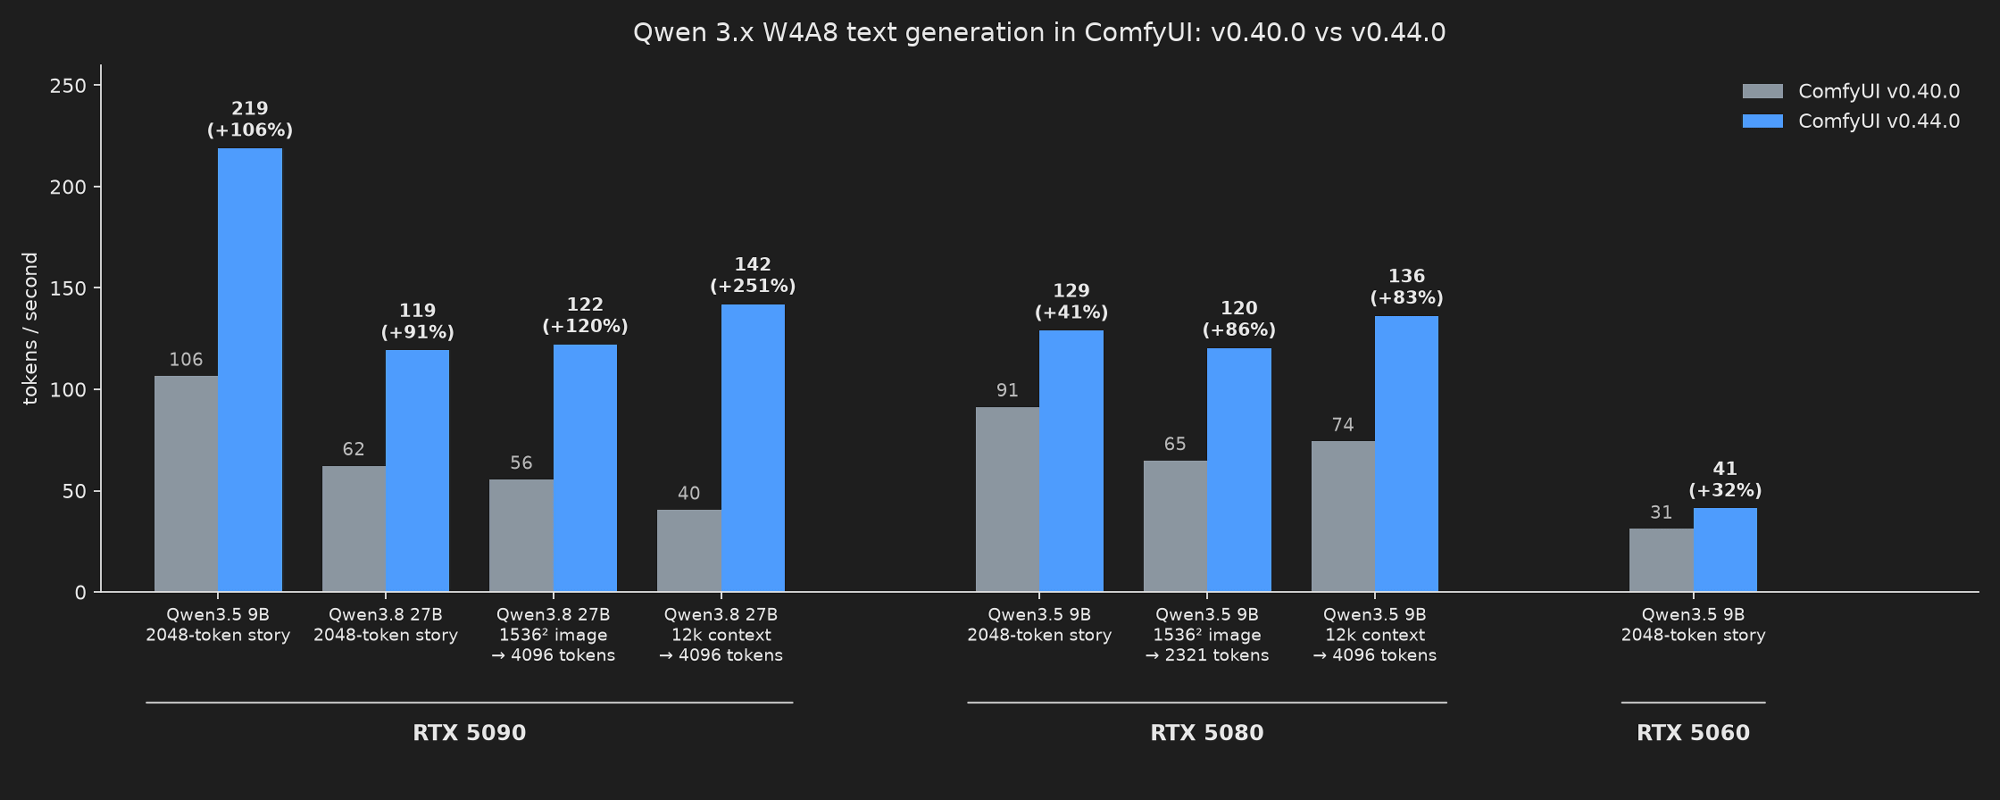
ComfyUI has specifically optimized for the Qwen3.5 series and Qwen3.8 series, with performance improvements seen with each version update. The graph below compares the text generation speed between version 0.40.0 and 0.44.0, showing that on an RTX 5090, tasks such as "generating 2048 tokens of text with Qwen3.5 9B" and "reading a 1536×1536 pixel image with Qwen3.8 27B and generating 4096 tokens of text" have seen speed improvements of more than double.
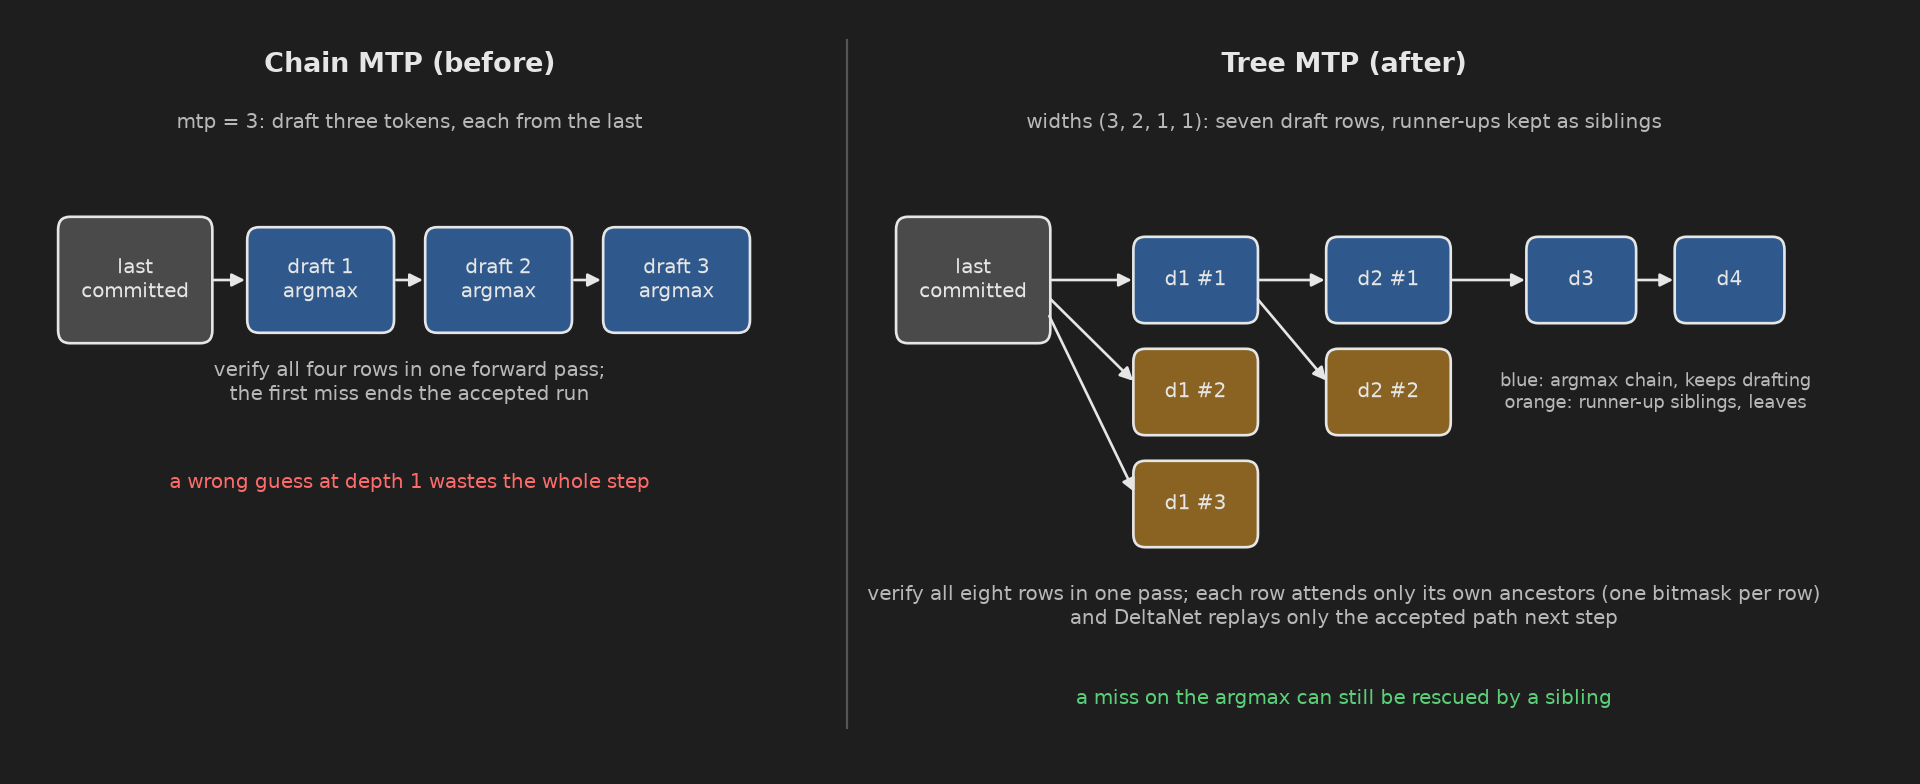
One of the major factors contributing to the speed improvements is the tree-structured MTP algorithm. MTP is a mechanism that uses a smaller draft model to predict subsequent tokens during text generation. Previously, ComfyUI used a chain-structured MTP algorithm where "prediction with the draft model is completed before predicting the next token," which resulted in significant wasted processing when predictions were incorrect. With the update, the tree-structured MTP algorithm, which "processes predictions across multiple branches rather than just one," has been implemented, enabling more efficient processing with less waste.
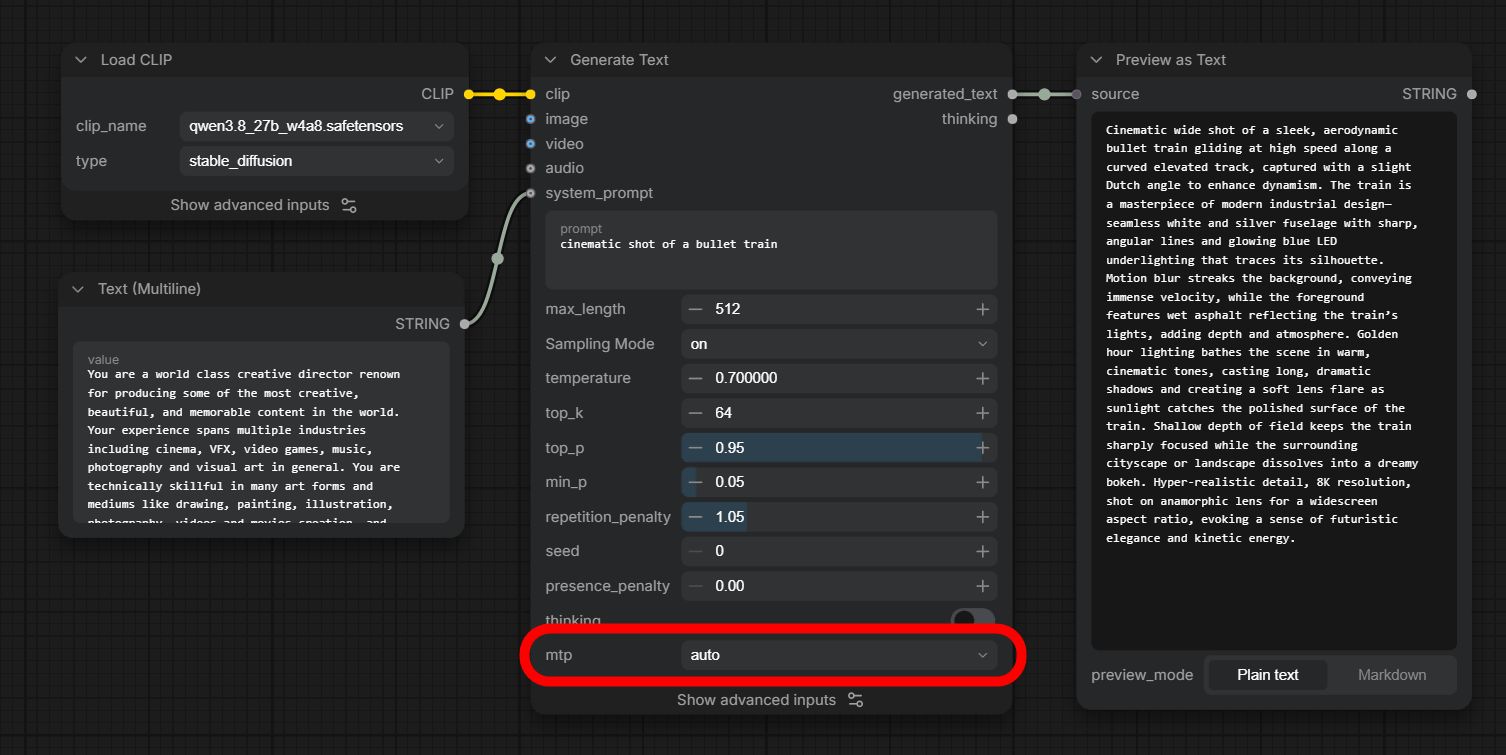
To use the tree-structured MTP algorithm, simply set the "mtp" field in the "Generate Text" node to "auto."
Additionally, ComfyUI's official workflows have adopted the "W4A8" quantized model format, and the linear kernel has been optimized to improve the processing efficiency of W4A8 quantized models. Furthermore, the high-speed attention mechanism used in image and video generation, "Comfy-Kitchen attention," is now also available for text generation.Comfy-Kitchen attention
The aforementioned improvements are compatible with both Windows and Linux systems and are effective on NVIDIA and AMD GPUs. To use Comfy-Kitchen attention, simply add the "--use-ck-attention" option to the ComfyUI startup command.
Other improvements are automatically applied by updating ComfyUI.



