410, according to MDN, means that the content has been permanently removed and there is no address to redirect to. 403 means that the client does not have access rights and the server refuses the request. 429 — a request-rate limit; the page itself may be intact. 503 — a temporary condition; the server may specify the recovery time in the Retry-After header. 401 can be a standard response to a Cloudflare security check: the visitor has not actually been blocked. A script that considers any page with an error dead would mark an extra thirty or so addresses as dead based on this data.
The script categorizes addresses using the same categories as the code table, plus two administrative categories: no response and manual parsing. Save the code in a file named check.py, put the addresses in a file named urls.txt, one per line, install the requests library, and run it in the terminal from that directory: python3 check.py urls.txt.
import sys
import requests
s = requests.Session()
s.max_redirects = 10s.headers["User-Agent"] = "link-check/1.0 (checking links from AI answers)"
def check(url):
try:
r = s.get(url, timeout=(5, 15), allow_redirects=True, stream=True)
r.close()
except requests.exceptions.RequestException as e:
return "no response", type(e).__name__, url
code = r.status_code
if 200 < code < 300:
return "alive", code, r.url
if code in (404, 410):
return "removed", code, r.url
if code in (401, 403, 429, 503):
return "closed to bots", code, r.url
return "review manually", code, r.url
for url in open(sys.argv[1]).read().split():
print(url, *check(url), sep="\t")
GET instead of HEAD. HEAD returns only headers without a body, so the script will not see the page text with it. GET leaves the option to add a content check; in the script above, I do not read the body.
Up to 10 redirects. A link that leads to an article through a redirect is alive as far as the reader is concerned. The number 10 is taken from Google’s crawlers: by default, they follow the chain for up to 10 redirects. If you switch to HEAD, you will have to explicitly enable redirects in Requests with the allow_redirects parameter.
A timeout of 5 seconds for connecting and 15 seconds for reading. Without it, Requests may wait for a response indefinitely. The library reports timeouts and excessively long redirect chains with exceptions; they have no response codes, so the script catches them separately and writes: no response. The numbers themselves are my choices and can be challenged.
Custom User-Agent. The script presents itself as a link checker and does not disguise itself as a browser.It will not pass Cloudflare’s security check: it is JavaScript-based, and the script will receive the check itself instead of the page. URLs categorized as closed to robots should be opened in a browser.
The final URL in the last column. If it differs from the original, the page was moved or redirected to the homepage, and the script will mark it as live in either case. Such rows should be read manually.
Why an AI search engine cites a deleted article
Most likely because the AI’s search index lags behind the websites: the article has already been deleted, but the crawler has not yet reached it. Pages are deleted all the time. According to Pew Research Center, a quarter of the pages that existed in 2013–2023 had become unavailable by October 2023, and most often it was a single page on a working website that was deleted. Perplexity says that it is often impossible to reindex every URL and that a machine-learning model decides what to crawl and when. Therefore, a deleted page may remain in its index until the crawler reaches it. OpenAI publishes a timeframe only for changes to robots.txt—about 24 hours—and does not give a timeframe for removing pages from ChatGPT Search.
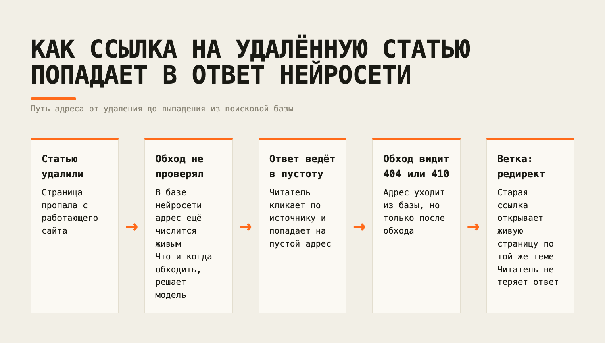
Between the deletion and the crawl, only a redirect keeps the link alive; the other nodes do not depend on the site’s author.
At least conventional search engines explain what they do with a deleted page. For 4xx responses other than 429, Google continues to report that the content is unavailable, and previously indexed URLs eventually stop being used. Yandex removes a page returning a 404, 403, or 410 response from the search index within a week after the crawler detects it, but it may take some time for the crawler to reach the page.Yandex’s index also contains 403 responses: it removes pages blocked from crawlers from the index as well.
What to do with your page before deleting it: set up a redirect to a page on the same topic
A link to a deleted page may remain in AI responses, so before deleting it, you should set up a redirect from it to an up-to-date page on the same topic. The instruction for whoever manages the website is this: configure a permanent redirect from the old URL to the chosen new URL and check in a browser that the old link opens the new page. Then someone clicking the old link in the response will reach live content. A redirect to the homepage will also be shown as live by the script, but the reader who came from the AI response will not find there what they were promised. If there is no replacement, return 410: according to MDN, this is a clear signal that the content has been permanently removed.
In my test, there were around six hundred URLs from a single measurement, and none of them were invented. The fear that AI invents links is outdated for search-enabled services: they link to real pages that once existed. The real problem is a stale index: a deleted page continues to serve as a source. Therefore, what needs to be checked is not whether the URL exists, but whether it is live and whether the page says the same thing as the AI paraphrased.
Limitations: one measurement and a check of only whether the page opens
This is a single measurement: around six hundred URLs from the responses of five AI models, checked one month later. Whether the dead articles were removed before the AI’s response or during that month, a single check cannot tell the difference. On other datasets, the picture is sometimes worse: the Tow Center’s study of news citations found invented or broken URLs in more than half of Gemini’s and Grok 3’s responses.I haven’t checked whether the page that opens says the same thing as the neural network paraphrased, and the live source may turn out to be unreliable: a fabricated concept in an arXiv preprint was cited by 8 out of 10 AI search engines on readily accessible platforms within a week. As for how long a link in a neural network’s response generally remains live, I compared this across three runs of 20 questions each. But how long does an already deleted page persist in the responses—does anyone have measurements like that?


