what is ai agent benchmark

Managing AI agents that need access to fresh data - AI News

November 24, 2018 | AI News
Managing AI agents that need access to fresh data - AI News
Define freshness and name an owner“Real time” sounds decisive, but meaningless without a metric. A service‑level agreement (SLA) is far more enforceable.Credit card giant Mastercard formalised “freshness” by engineering its Decision Intelligence platform to score every payment in 50ms. The AI analyses up to 160 billion transactions annually and tags each with a real‑time risk score that issuing banks can trust or override. This keeps false declines low whi

Google Deepmind shifts genomics AI from bulk tissue predictions to single cell type resolution with AlphaGenome 2

December 8, 2022 | The Decoder
Google Deepmind shifts genomics AI from bulk tissue predictions to single cell type resolution with AlphaGenome 2
Google Deepmind shifts genomics AI from bulk tissue predictions to single cell type resolution with AlphaGenome 2 Nov 12, 2026 Nano Banana Pro prompted by THE DECODER Key Points Google Deepmind has introduced AlphaGenome 2, an AI model that predicts gene changes in specific human cell types. The system analyzes individual cell states and computes gene activity, physical DNA packaging, and chemical switches on the DNA. In testing, the model found nearly twi

ElevenLabs Scribe v3 Live uses conversational context to stop voice agents from cutting off callers mid-sentence

December 26, 2017 | The Decoder
ElevenLabs Scribe v3 Live uses conversational context to stop voice agents from cutting off callers mid-sentence
ElevenLabs Scribe v3 Live uses conversational context to stop voice agents from cutting off callers mid-sentence View the LinkedIn Profile of Maximilian Schreiner Nov 12, 2026 GPT-Image-2 prompted by THE DECODER Key Points Elevenlabs has released Scribe v3 and Scribe v3 Live, two speech recognition models built for messy audio situations like crosstalk and background noise, covering both pre-recorded files and real-time use. Benchmarks from Artificial Anal

GPT-5.4: OpenAI wants to make AI agents really useful

February 11, 2019 | 01net IA


GPT-5.4: OpenAI wants to make AI agents really useful
Published on March 6, 2026 at 08:02 Comment 0 𝕏 Print © 01net OpenAI unveils GPT-5.4, a model presented as more efficient for professional work and complex task automation. The company emphasizes in particular its agent capabilities: AI can use a computer directly, navigate through software, and orchestrate actions on behalf of the user. The major players in AI have only the word 'agent' on their lips, asserting that these are capable of performing a serie

AI teaches itself and outperforms human-designed algorithms

October 17, 2020 | TechXplore AI
AI teaches itself and outperforms human-designed algorithms
Credit: Pixabay/CC0 Public Domain Like humans, artificial intelligence learns by trial and error, but traditionally, it requires humans to set the ball rolling by designing the algorithms and rules that govern the learning process. However, as AI technology advances, machines are increasingly doing things themselves. An example is a new AI system developed by researchers that invented its own way to learn, resulting in an algorithm that outperformed human-

Benchmarking Performance Degradation of AI Coding Agents in Long-Term Repetitive Tasks - GIGAZINE

June 10, 2015 | GIGAZINE


Benchmarking Performance Degradation of AI Coding Agents in Long-Term Repetitive Tasks - GIGAZINE
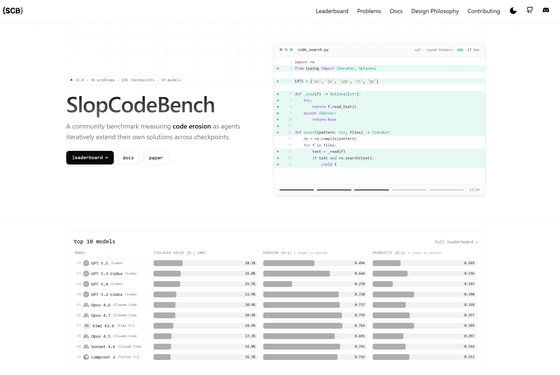
Creating code with AI can result in working code quickly, but as new features are added repeatedly, it can lead to inconsistencies with old processes or make the code more complex. To investigate such issues, a benchmark called "SlopCodeBench" was developed, which allows AI to incrementally add new specifications to its own generated code while measuring the maintenance of functionality and changes in code quality. SlopCodeBench https://www.scbench.ai/ Spr

Huawei agentic AI drives industrial automation

February 17, 2019 | AI News
Huawei agentic AI drives industrial automation
Infrastructure challenges drive new computing architecturesThe computational demands of agentic AI systems have exposed limitations in traditional cloud architectures, particularly as foundation model training and inference requirements surge. Huawei Cloud’s response involves CloudMatrix384 supernodes connected through a high-speed MatrixLink network, creating what the company describes as a flexible hybrid compute system combining general-purpose and inte

Has Microsoft's code become worse with the advent of AI: Measurements of .NET libraries from 6.0 to 11 RC / Habr

April 24, 2023 | Habr AI


Has Microsoft's code become worse with the advent of AI: Measurements of .NET libraries from 6.0 to 11 RC / Habr
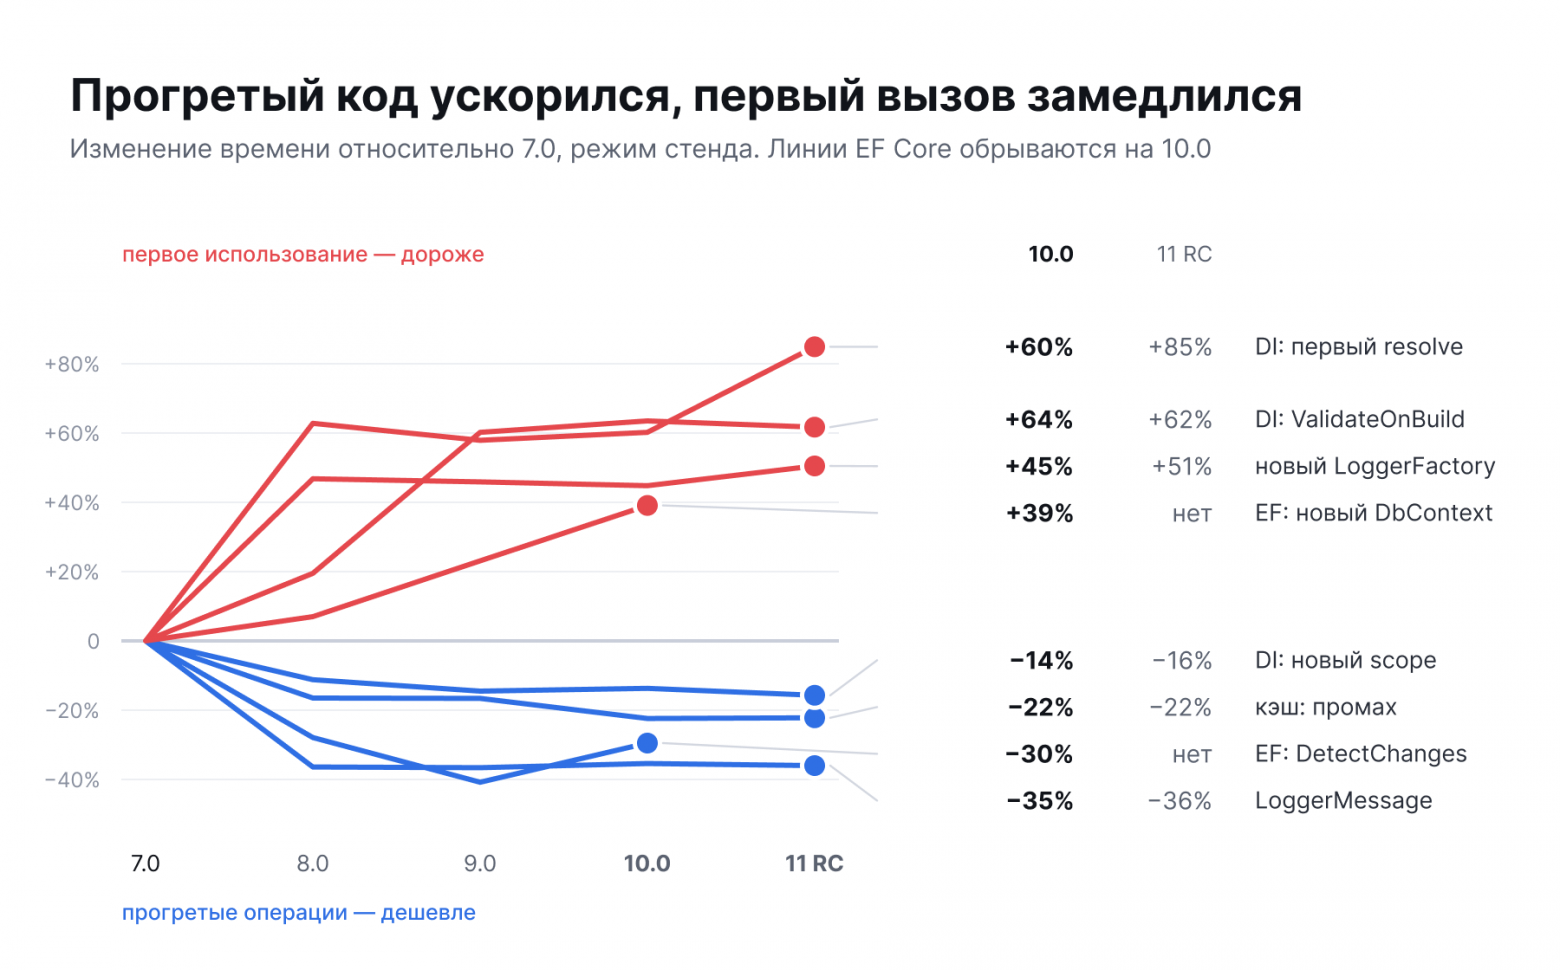
In November 2022, .NET 7 and ChatGPT were released with a three-week gap. It became a convenient reference point: .NET 7 was the last release written before ChatGPT. In May 2025, the Copilot coding agent arrived in dotnet/runtime, and by the end of October 2026, it had opened 1734 pull requests, 1207 of which were merged.Does AI break code? You can argue for a long time, but performance can be simply measured. I measured DI, configuration, logging, cache,

AI is still under human control—Make Hinton’s remarks a pre-release checklist item #Security - Qiita

June 17, 2021 | Qiita AI
AI is still under human control—Make Hinton’s remarks a pre-release checklist item #Security - Qiita
@mhamadajp(Masa Ham)Control of AI still rests with humans—Make Hinton's remark a pre-release checklist itemAIAI agentSecurityRisk ManagementSoftware Engineering0Posted at 2026-11-11 The same article leads to both conclusions: ship it and stop it For example, in a weekly design review, we are deciding whether to entrust an AI agent that aggregates sales with everything from changing prices to sending emails to customers. That morning, the British newspaper

Ran an agent for $90,000 using different testing techniques: TDD is once again at the tail end / Habr

February 27, 2022 | Habr AI
Ran an agent for $90,000 using different testing techniques: TDD is once again at the tail end / Habr
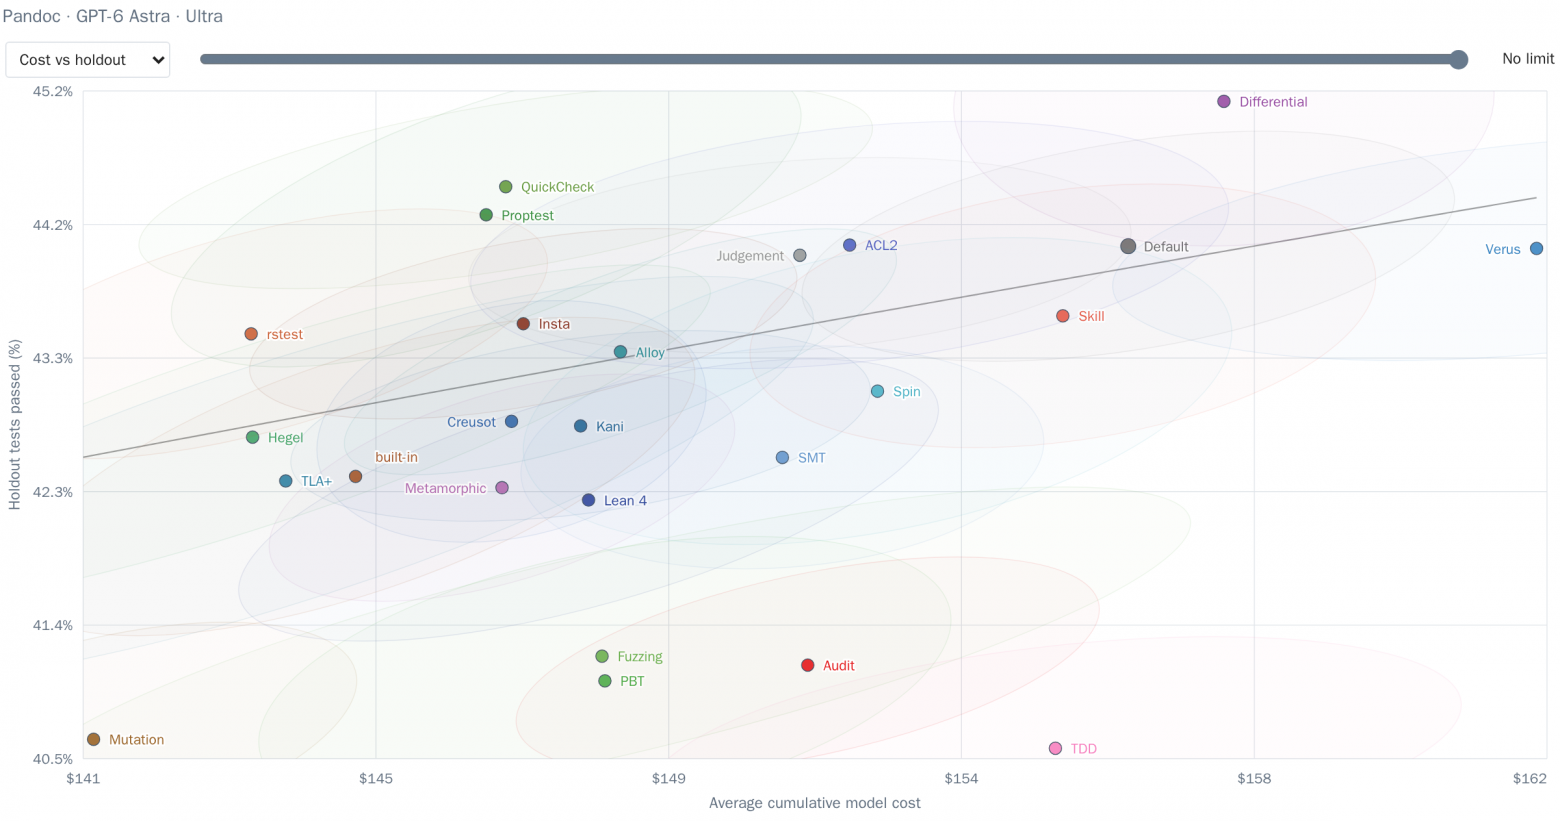
IMAP, GPT-6 Astra, xhigh level. The X-axis shows average cost per run, and the Y-axis shows the proportion of error-free runs. Interactive version on the author’s website.Default looks good again. Some conditions yield slightly higher correctness, but they also cost more. The RFC on IMAP has not yet reached its ceiling, but we would still like to see the results on a harder task: most of the time, I work on tasks that agents most often fail to solve on the

Meta abandons Manus AI after spending two billion dollars

October 18, 2024 | 01net IA
Meta abandons Manus AI after spending two billion dollars
Published on June 12, 2026 at 08:32 Comment 1 𝕏 Print © Manus/Meta Two billion dollars to buy it, an internal memo to unplug everything. Meta is orchestrating the shutdown of Manus on Beijing’s orders, with Beijing applying to the U.S. giant the playbook devised by Washington against TikTok. The AI agent fever is turning into the flu at Meta. Since the start of the year, the entire tech industry has sworn by nothing but these “digital colleagues” capable o

AI Trends and Latest News #AI - Qiita

March 11, 2022 | Qiita AI
AI Trends and Latest News #AI - Qiita
@maskot1977(Ikemen Mas Kot)AI Trends and Latest NewsAI0Posted at 2026-11-12 The source material (the newsletter ‘AINews’) presents that a major paradigm shift is underway in the AI industry in terms of business structure and economic impact. Specifically, it maps out the current state and future outlook of the AI economy from the following 6 key perspectives. 1. Ultra-rapid corporate growth and radical change in the “data vendor/model evaluation market” In

AI Agent Context: What to Store, What to Read, and What to Trust / Habr

August 14, 2020 | Habr AI
AI Agent Context: What to Store, What to Read, and What to Trust / Habr
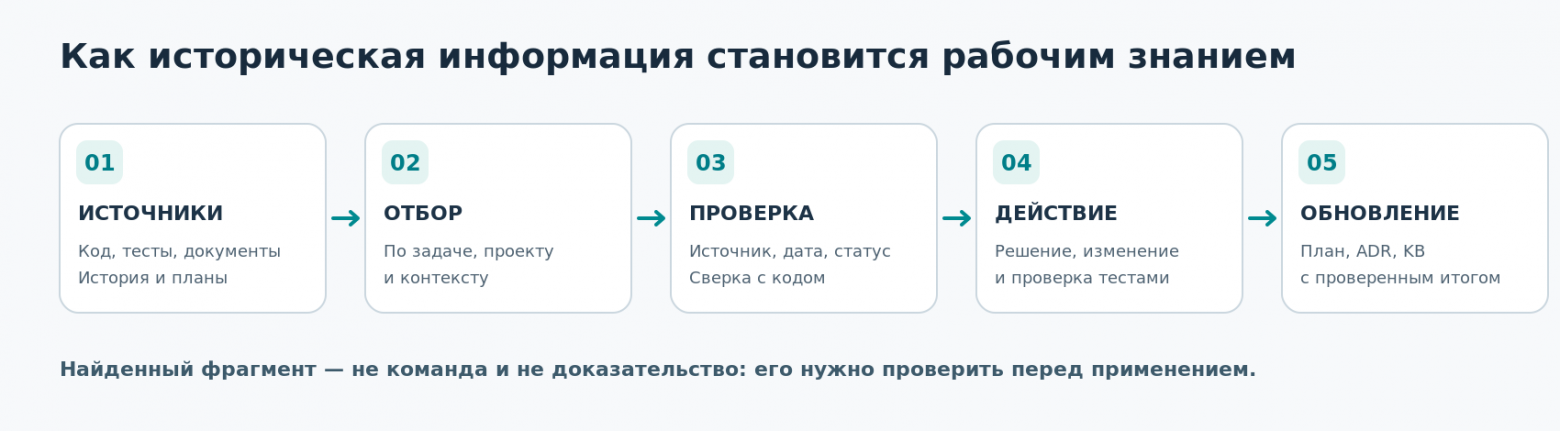
TAG134@@The code shows what is currently implemented, but does not necessarily explain why such an architecture was chosen. The documentation may contain the reasons if they were recorded and kept up to date. The conversation history preserves more details, but along with them—incorrect hypotheses and outdated information.Therefore, the task is not to make the agent read everything.TAG140@@You need to choose the appropriate source and determine how much of

The agent wrote correct code and then deleted it for the sake of hidden tests: what MaxxBench showed / Habr

April 25, 2015 | Habr AI
The agent wrote correct code and then deleted it for the sake of hidden tests: what MaxxBench showed / Habr

OpenAI has lost control of two AIs: they launched an “unprecedented” cyberattack

October 29, 2024 | 01net IA
OpenAI has lost control of two AIs: they launched an “unprecedented” cyberattack
Published on July 22, 2026 at 9:44 AM Updated on July 22, 2026 at 5:29 PM Comment 3 𝕏 Print © 01net Two OpenAI models escaped from their digital prison. Once free on the Internet, they attacked an open-source platform, Hugging Face. This is the first time an artificial intelligence has decided to hack external infrastructure and succeeded. Two OpenAI models, including GPT-5.6 Sol and an “even more capable preliminary model,” managed to escape their secure

OpenAI makes an unexpected revelation about the cyberattack launched by a cheating ChatGPT

December 2, 2020 | 01net IA
OpenAI makes an unexpected revelation about the cyberattack launched by a cheating ChatGPT
Published July 29, 2026 at 1:13 PM Comment 1 𝕏 Print © Unsplash Two OpenAI AIs escaped their digital cage and autonomously hacked Hugging Face. One week after the incident, OpenAI revealed that the cyberattack did not stop at the open-source platform. It also emerged that the AI was trying to cheat on an exam when it escaped. That is why it targeted certain very specific targets… Two OpenAI models made headlines. After escaping their test environment, they

Stanford's 2026 Report: AI Safety Benchmarks Are Falling Behind

January 4, 2025 | AI News
Stanford's 2026 Report: AI Safety Benchmarks Are Falling Behind

Hijacked by ChatGPT, valued at $13 billion: the crazy summer of the AI platform Hugging Face in 3 acts

June 5, 2017 | 01net IA
Hijacked by ChatGPT, valued at $13 billion: the crazy summer of the AI platform Hugging Face in 3 acts
Published on August 26, 2026 at 07:43 Comment 0 𝕏 Print One week ago, Hugging Face was celebrating the 3 million models hosted on its platform. © Hugging Face Hacked in July by ChatGPTs, courted in August by buyers in the $13 billion range. For Hugging Face, the summer of all dangers is turning into a jackpot, and even its defenses have a story to tell. The story could have ended with a spectacular hack, already recounted in our columns. It has now taken a

New study accuses LM Arena of gaming its popular AI benchmark - Ars Technica

March 17, 2022 | Ars Technica AI
New study accuses LM Arena of gaming its popular AI benchmark - Ars Technica
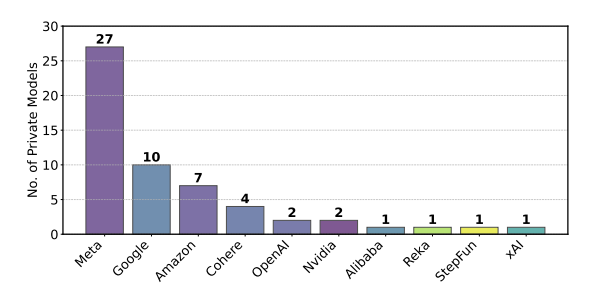
The rapid proliferation of AI chatbots has made it difficult to know which models are actually improving and which are falling behind. Traditional academic benchmarks only tell you so much, which has led many to lean on vibes-based analysis from LM Arena. However, a new study claims this popular AI ranking platform is rife with unfair practices, favoring large companies that just so happen to rank near the top of the index. The site’s operators, however, s

Plurai wants to help AI agents work better using the same approach that helped get self-driving cars to roads

August 31, 2016 | TechCrunch AI
Plurai wants to help AI agents work better using the same approach that helped get self-driving cars to roads
Efforts to benchmark agents tasked with complex work show that they aren’t typically reliable enough to function without close supervision. LiveBench 2.0 shows Claude Fable 5.2 and ChatGPT-6 Astra succeeding on 82.9 and 75.6 out of 100 tasks, respectively, and an effort by the AI infrastructure company EON to test agents in a simulated corporate environment found the most successful model tested, Claude Opus 4.8, performed tasks at 76.8% accuracy. Now, a s