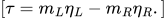 Here, where
 127@@the efficiency of physical actuators. (What’s so hard about that?)
And here is the most important point: the neural network no longer does a damn bit of static classification.
Now its output changes the position of the body. The change in position affects the receptor readings. New signals enter the network again.
A closed loop is formed:
Receptors → neural network → motors → physical body → environment → receptors.
The state of the organism depends not only on the current input signal, but also on the entire preceding trajectory of interaction.
This is now a control problem involving a dynamic system with feedback.
And this is exactly where I wanted to observe learning.
Why SPORE was so important to me
One of the first questions I encountered was: what does “a synapse learns” actually mean?
In the simplest case, one can use Hebb’s rule:
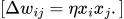
The activity of the sending and receiving neurons determines the change in the strength of the connection.But simply enhancing correlated activity does not tell us whether the behavior it elicited was beneficial.
One can introduce a third factor—a modulating signal functionally analogous to reinforcement, honestly predict it, but the numbers fall apart.
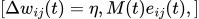
where

the local trace of activity,
 TAG163@@a signal influencing learning.
Now it becomes possible to link local neural events with external consequences.
But a problem arises: if the reward comes several steps after the action, which synapse exactly should receive the positive update?
And how many synapses deserve punishment if the organism fails to reach the goal?
What interests me about SPORE specifically is that it investigates learning in spiking networks through reinforcement and stochastic synaptic plasticity.
In the stochastic approach, the parameter update can simultaneously include the directed action of the objective function, an a priori constraint, and random diffusion.
In general, it is convenient to represent this dynamics as:
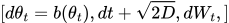
where:

the directed drift of the parameters, (D) — the intensity of diffusion, and (W_t) — a Wiener process.
This is already a fundamental departure from the notion of a neural network as a static matrix of fully learned weights.
Synapses can continue to change.
However, continuous variability by itself still does not mean learning.
A random walk is not intelligence.
For useful adaptation to arise, the changes must statistically improve behavior in the environment of interest.
TAG196@@
TAG198@@
TAG200@@192@@
And this moment proved decisive for my entire research.
e-prop and the problem of responsibility
Another direction I explored was eligibility propagation, or e-prop.
In a recurrent neural network, the result of an action depends on a set of states spread over time.
The question is how to compute a useful change in parameters without fully storing and backpropagating the entire history of the dynamics.
One of the central ideas behind e-prop is decomposing the gradient into local eligibility traces and learning signals:
![\sum_t L_j(t)e_{ji}(t), ]](https://habrastorage.org/getpro/habr/formulas/f/fc/fc4/fc4c7dceb6a4870f69f3116501772526.svg) TAG206@@where
 TAG209@@characterizes the local sensitivity of the neural dynamics to the parameter, andTAG211
is the learning signal. With an exact learning signal, this decomposition makes it possible to represent the gradient; practical versions of e-prop use approximations that are available when running the network.
TAG214@@What interests me here is not so much the derivative itself as a philosophical question.TAG216How does a local element of the system learn about the global outcome?TAG219A neuron does not see the entire trajectory of the body.
TAG222@@A synapse does not know the coordinates of the food source.TAG224@@A motor does not know how useful the command will prove to be ten steps later.TAG226@@Nevertheless, the system must somehow distribute responsibility for the outcome among an enormous number of local events.TAG228@@This is not a rhetorical question.TAG230@@This is a concrete mathematical problem.TAG232@@And Z3R0 allowed me to explore it through a physically interpretable example.TAG234@@I broke my organism’s bodyTAG236@@СнAt first, I modeled damage to one motor.For example:

The left actuator became weaker than the right.
It would seem that the neural network now needed to acquire a new compensatory skill.
But the control tests revealed something unpleasant.
Across 4,000 independent worlds, the base network demonstrated a 40.1% success rate with an intact body and 39.3% with one motor weakened.
The difference was only 0.8 percentage points.
It turned out that the existing sensorimotor loop had already partially compensated for the damage through feedback.
And then I realized the fundamental error in the way the question was framed.
It is impossible to prove the acquisition of a new skill if the original skill has barely been impaired.
I had to change the experiment itself.
I swapped the motor commands.
Instead of the usual torque:
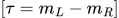
I got:
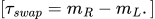
Now the previous control began operating in reverse.
For one base network, the success rate fell from 40.1% to 10.4%.
That was a real adaptation stress test.
But before demanding training, I decided to check another fundamental question.
Is there a useful solution at all within the accessible synaptic weight space?
I froze the internal neural network and used an external Evolution Strategies algorithm to search for the weights feeding into the motor neurons.
The weight was parameterized via a bounded coordinate:

This parameterization preserves the original sign of a nonzero sthe connection and limits the change in its absolute magnitude by factors of approximately 0.301 to 3.320.
On a single organism, external optimization increased the post-Swap success rate from 10.4% to 33.2%.
In a cohort of ten organisms, the average success rate of the discovered ES configurations reached 44.68%, compared with 24.18% for the original frozen networks.
This is not an absolute theoretical limit, nor is it proof of the ability to learn independently.
But the experiment showed something important: within the tested constrained parameter space, there exist configurations that provide substantially better control of the damaged body.
In other words, the problem was not simply a lack of permissible useful weights.
The hardest part remained.
To teach the organism to find them on its own.
SMSS: when a beautiful equation does not become intelligence
Building on the approaches studied, I experimented with Motor Synaptic Sampling — SMSS.
In the configuration used, a Gaussian perturbation is added to the motor pre-activation:
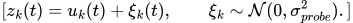
The motor command then passes through a sigmoid function:
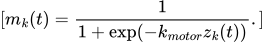
For a Gaussian policy over noisy pre-activation, the score function gives:
![\frac{\xi_k}{\sigma_{probe}^2} \frac{\partial u_k}{\partial\theta_i}. ]](https://habrastorage.org/getpro/habr/formulas/5/52/524/5247fc59fadbdca7e8bd1c2c6a2904b6.svg)
This makes it possible to form synaptic traces linking the parameters of the motor reader with exploratory perturbations.
The accumulated signal is used in updating the parameters, which in our implementation combines a gradient component, a prior anchor, and Langevin noise:
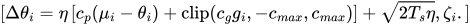
Here

The estimate of the learning gradient based on the accumulatedm traces,

the stochastic sampling intensity parameter,

standard normal noise.
Mathematically, the approach is interesting.
But I return once more to my main point.
The presence of a training signal in the equation does not prove that useful learning exists.
Therefore, control experiments were conducted: frozen weights, gradient-free sampling, full SMSS, and separate external ES optimization.
In ten organisms, after 200 episodes of individual life, the results were as follows:
Method | Success rate |
|---|---|
Frozen | 24.18% |
Zero-Gradient | 23.62% |
| Full SMSS | 22.02% |
ES configurations found | 44.68% |
The difference between SMSS and Zero-Gradient was −1.60 percentage points.A paired statistical test yielded (p≈0.098).
We found no compelling evidence that, in this configuration, the SMSS learning component provides an advantage over the gradient-free control.
And I am not going to call this a victory.
The synaptic weights did indeed change.
But we did not demonstrate in vivo recovery of the skill in the tested condition.
I could show several successful trajectories, write about plasticity, add a beautiful visualization of the neurons, and declare that the artificial organism had learned to adapt to the damaged body.
But then I would no longer be investigating intelligence.
I would instead be investigating my own desire to find it.
What I have learned over these years
I have realized that in neuromorphic research, it is not enough to build neurons that spike. It is not enough to write down Hebb’s rule. It is not enough to add dopamine.It is not enough to make a random change to the weights and obtain an improvement over several episodes.
One must distinguish correlation from causality, randomness from directed search, and the robustness of an existing controller from the acquisition of a new skill.
And most importantly, one must be able to prove that a particular learning mechanism produces an effect that does not occur without it.
That is precisely what control groups are for.
And when my hypothesis failed to withstand scrutiny, I did not obtain a beautiful answer about the origin of intelligence, but a much more modest result: for the selected organism, physical task, and algorithm that simply adds stochastic synaptic plasticity, this was insufficient.
This does not disprove SPORE. It does not disprove e-prop. It does not disprove local learning, and still less does it say anything definitive about the nature of intelligence.
This is a limited negative result from my own implementation, reproducible under the protocol described.
And it is important to me.
Because I no longer want to replace the absence of an answer with a beautiful hypothesis.
Now I am interested in the following question: if an organism cannot effectively determine the consequences of its own motor perturbations from delayed reinforcement alone, can it learn to predict those consequences?
For example:
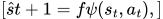
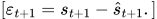
Tuta =) :
 TAG448@@an internal predictive model, and
 TAG451@@the error between the expected and actual sensory state.
Such an architecture could give the system additional information about how its own actions change the world.However, building an accurate predictor does not by itself guarantee improved control. This is a new, testable hypothesis, not an already established result.
It is precisely from such distinctions between what is possible, what is presumed, and what has been proven that I now begin every experiment.
I do not know where intelligence begins.
I do not know whether memory, plasticity, prediction, an internal model of the body, or something else is sufficient for it.
I do not know whether a small spiking network can become the foundation of a more universal learning organism.
But I know one thing: if I ever see behavior in Z3R0 that I did not anticipate, the first thing I will try to do is refute it.
I will disable learning.
I will shuffle the signals.
I will freeze the weights.
I will change the initial states.
I will test in independent environments.
I will try to find the simplest alternative explanation.
And only if the effect survives these tests will I allow myself to call it an acquired skill.
Because I do not need an artificial intelligence whose existence I have convinced myself of.
I want to find one whose existence I can prove.
Thank you to everyone engaged in this science. Thank you to the authors of SPORE, e-prop, NEST, BindsNET, Brian2, Norse, and many other works that I have not yet gotten to.With the Mozhdovatelsk model.But that doesn’t make every experiment conducted meaningless.
I continue not because I’m certain of victory.
I continue because I want to know.
Thank you for reading.
Arthur Valiyev, EVERTY.
To the dreamers! =)

