claude sonnet benchmark
Claude sonnet benchmark explained — what it is, how it works and what it costs. Below are 4 articles about claude sonnet benchmark on CheapToken News. This is one of the main topics we track on CheapToken News.
METR finds Anthropic may have crossed its own AI acceleration warning threshold back in July Maximilian Schreiner View the LinkedIn Profile of Maximilian Schreiner Nov 6, 2026 Anthropic AI News Without the Hype – Curated by Humans Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section. Subscribe now { "@context": "https://schema.

Synced reports Anthropic's most closely guarded mysterious “Model 4”,has been exposed! After secretly training from September to October, its internal comprehensive capability index (AECI) soared to the astonishing score of 178.6; the existing test battery can barely hold it back anymore. Today, the third-party evaluation organization METR released a major investigation. After grinding through 11 straight weeks and digging deep into Anthropic's sensitive i
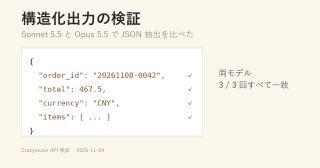
@whitemarshallResults from Testing Structured Output with Claude Sonnet 5.5 and Opus 5.5: Where Did JSON Extraction Fail?AILLMPythonTAG21TAG230

Anthropic released Claude Sonnet 5.5 on September 28, and OpenAI released GPT 6.1 Sol on September 29. Coincidentally, the two models have exactly the same listed API prices on OpenRouter: $2 per million input tokens and $10 per million output tokens. Leiphone(WeChat public account: Leiphone) The two companies are moving in highly similar directions: compressing the capabilities of near-top-tiermodels into a product tier that is faster, cheaper, and suited