Tag: what is qwen llm inference cost
Compare what is qwen llm inference cost — the latest prices, options and news, all in one place. Below are 2 articles about what is qwen llm inference cost on CheapToken News. It is part of our llm inference cost coverage.
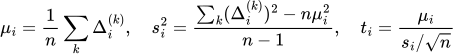
3. Activation heatmap3.1. Capturing activations with hooksThe model is loaded in BF16, the LoRA adapter is merged into the weights (merge_and_unload), and a forward_pre_hook is attached to the input of each mlp.down_proj. The input to down_proj is precisely the vector h:modules = [(name, m) for name, m in merged.named_modules() if name.endswith("mlp.down_proj")] def make_hook(name): def hook(module, args): hidden = args[0] # [batch, seq, 17408] flat = hidd
Copy link Facebook X Whatsapp Reddit Pinterest Flipboard Email Share this article Join the conversation Add us as a preferred source on Google Newsletter Subscribe to our newsletter Alibaba’s Qwen 3.8 27B open-weight AI model came out a couple of weeks ago, and it immediately created a wave of hype among local AI enthusiasts thanks to its impressive intelligence benchmark results for a model of its size and capabilities.Totaling around 17GB for four-bit qu