Tag: ai video generation pricing per token

Choosing Between Voice Live API Avatars—Configuration and Implementation for Standard, Custom Photo, and Custom Video #AI - Qiita

October 21, 2018 | Qiita AI
Choosing Between Voice Live API Avatars—Configuration and Implementation for Standard, Custom Photo, and Custom Video #AI - Qiita
@miyaura(Miyaura)Choosing between avatars for the Voice Live API - Configuration and implementation for standard, custom photo, and custom videoAzureMicrosoftFoundryVoiceLiveAPIavatarAI0Last updated at 2026-11-10Posted at 2026-11-10 Make agents speak with unique avatars using the Voice Live API Microsoft Foundry's Voice Live API is an API for creating agents that converse using voice, handling speech recognition, response generation, and speech synthesis t
Google wants video AI to understand what people need as they work

December 21, 2025 | The Decoder
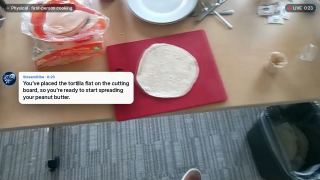
Google wants video AI to understand what people need as they work
Google wants video AI to understand what people need as they work Jonathan Kemper View the LinkedIn Profile of Jonathan Kemper Nov 1, 2026 Liu et al. AI News Without the Hype – Curated by Humans Subscribe to THE DECODER for ad-free reading, a weekly AI newsletter, our exclusive "AI Radar" frontier report six times a year, full archive access, and access to our comment section. Subscribe now { "@context": "https://schema.org", "@type": "NewsArticle", "headl

Google's Gemini Omni 1.2 Flash stretches AI video clips to 15 seconds and cuts pricing by 30 percent

August 3, 2026 | The Decoder
Google's Gemini Omni 1.2 Flash stretches AI video clips to 15 seconds and cuts pricing by 30 percent
Google's Gemini Omni 1.2 Flash stretches AI video clips to 15 seconds and cuts pricing by 30 percent Matthias Bastian View the LinkedIn Profile of Matthias Bastian Nov 5, 2026 Ask about this article… Search Google Deepmind is making its Gemini Omni 1.2 Flash video-generation model generally available. The updated model creates clips up to 15 seconds long, supports conversational editing, and costs 30 percent less than its predecessor. Google says Gemini Om

Distinguishing Character Drift in AI Videos by Locking Reference Images: Input Management and Quality Inspection Design #Python - Qiita

July 29, 2015 | Qiita AI
Distinguishing Character Drift in AI Videos by Locking Reference Images: Input Management and Quality Inspection Design #Python - Qiita
@movmixaiUsing a fixed reference image to isolate character drift in AI videos: input management and quality assurance designAIgenerative AIPython0Posted at 2026-11-09When working with the same character across multiple AI video clips, looking only at differences in the output makes it impossible to determine which change to the reference image, prompt, template, or model affected the results. In this article, we organize a method for managing inputs and t

ChatGPT: A 2025 timeline of updates to OpenAI’s text-generating chatbot

June 3, 2020 | TechCrunch AI
ChatGPT: A 2025 timeline of updates to OpenAI’s text-generating chatbot
In 2025, OpenAI has battled the perception that it was ceding ground in the AI race to Chinese rivals like DeepSeek, all while the company has tried to shore up its relationship with Washington, pursued ambitious data center projects, and laid the groundwork for one of the largest funding rounds in history. Most recently though, headlines around OpenAI have focused on its competition gaining ground, with CEO Sam Altman’s “code red” internal memo shifting c

Meta says US users can now video chat with their Muse AI avatar

December 14, 2023 | TechCrunch AI
Meta says US users can now video chat with their Muse AI avatar
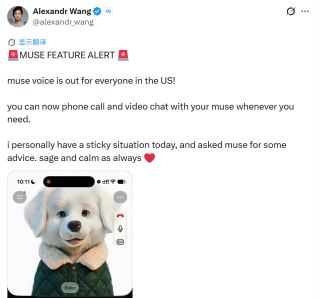
First introduced at Meta’s Connect developer conference in September, the video-chatting feature involves new AI models, Muse Realtime Avatar and Muse Realtime Voice technology, which help power the digital avatar that chats with the user. While other AI competitors offer voice chat features, Meta’s Muse offers a cute, animated avatar (nicknamed Jolly), which users interact with as they ask questions or request tasks to be handled on their behalf. Users ca

A Practical Workflow for Video Transcription and Subtitle Creation #AI - Qiita

June 20, 2019 | Qiita AI
A Practical Workflow for Video Transcription and Subtitle Creation #AI - Qiita
@gjsdkodahA Practical Workflow for Video Transcription and Subtitle ProductionAITranscriptionVideoSubtitlesWork Efficiency0Posted at 2026-11-09 How to Convert Recorded Study Sessions and Technical Explainer Videos into Searchable Text Recorded study sessions and demo videos can take time even just to review. I find it easier to follow a workflow in which I first convert them into searchable text and then organize them. 1. Benefits of Transcribing Video Con

You can now video call with Muse! Netizens are having fun: creating their own animated virtual avatars and letting AI characters role-play.

June 17, 2022 | 智东西
You can now video call with Muse! Netizens are having fun: creating their own animated virtual avatars and letting AI characters role-play.
Zhidx (WeChat official account: zhidxcom) Author | Sun Xiaowen Editor | Cheng Qian Zhidx reported on November 6 that Meta began opening its personal AI agent Muse’sreal-time voice and animated avatarfeatures to users in the United States early this morning. Users can create their own animated avatars for Muse and converse with them directly. The avatar changes its expressions and movements as the conversation progresses, much like being on a “video call.”

Learning to play Minecraft with Video PreTraining

July 28, 2021 | OpenAI News
Learning to play Minecraft with Video PreTraining
We trained a neural network to play Minecraft by Video PreTraining (VPT) on a massive unlabeled video dataset of human Minecraft play, while using only a small amount of labeled contractor data. With fine-tuning, our model can learn to craft diamond tools, a task that usually takes proficient humans over 20 minutes (24,000 actions). Our model uses the native human interface of keypresses and mouse movements, making it quite general, and represents a step t

Video generation models as world simulators

June 23, 2019 | OpenAI News
Video generation models as world simulators
We explore large-scale training of generative models on video data. Specifically, we train text-conditional diffusion models jointly on videos and images of variable durations, resolutions and aspect ratios. We leverage a transformer architecture that operates on spacetime patches of video and image latent codes. Our largest model, Sora, is capable of generating a minute of high fidelity video. Our results suggest that scaling video generation models is a