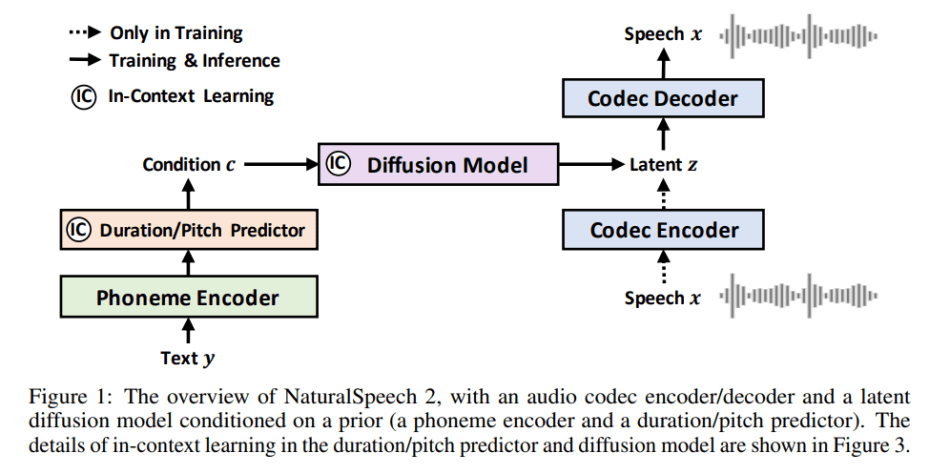
Contemporary text-to-speech (TTS) systems are achieving increasingly impressive humanlike voice generation performance in terms of intelligibility and naturalness. A lack of diverse speech data however makes it challenging to faithfully capture the many different speaker identities, prosodies and styles that can present in human speech. In the new paper NaturalSpeech 2: Latent Diffusion Models are Natural and Zero-Shot Speech and Singing Synthesizers, a Mi