ai multimodal model pricing per token
Compare ai multimodal model pricing per token — the latest prices, options and news, all in one place. Below are 18 articles about ai multimodal model pricing per token on CheapToken News. It is part of our ai token pricing coverage.

Image analysis of a refrigerator to measure and locate features. Credit: Fraunhofer IPK Household appliances need to be refurbished and/or recycled at the end of their useful lives. The KIKERP project (see below) aims to harness artificial intelligence to collect information about used appliances and determine parameters such as model and condition to help decide whether a particular device should be refurbished or recycled. In the case of recycling, the a

In recent strides within the field of Multimodal Large Language Models (MLLMs), while notable progress has been made in input-side multimodal comprehension, a notable void persists in the domain of multimodal content generation. Addressing this gap, a collaborative effort between Tencent AI Lab and The University of Sydney introduces GPT4Video in a new paper GPT4Video: A Unified Multimodal Large Language Model for lnstruction-Followed Understanding and Saf

From text and proteins to audio, images, and state sequences, decoder-only generative models have proven their ability to generate new sequences across various modalities. However, integrating multiple generative foundation models, especially those trained on different modalities, into a cohesive and superior system presents significant challenges. In a new paper Zipper: A Multi-Tower Decoder Architecture for Fusing Modalities, a Google DeepMind research t

The 6th annual BAAI Conference hosted by Beijing Academy of Artificial Intelligence (BAAI), commenced today in Beijing, marking a significant gathering for global AI insiders. This premier event, themed “Global Vision, Ideas in Collision, Leading Cutting-Edge Innovations,” brings together top researchers and industry leaders from around the world to share their latest findings and discuss the future of artificial intelligence.This year’s BAAI 2024 conferen

Large Language Models (LLMs) have advanced considerably in generating and understanding text, and recent developments have extended these capabilities to multimodal LLMs that integrate both visual and audio data. Despite these gains, these models still face challenges with fine-grained cross-modal temporal reasoning, especially in aligning events across audio and video streams. To address this, an NVIDIA research team has introduced OMCAT: Omni Context Awa

Recent advancements in training large multimodal models have been driven by efforts to eliminate modeling constraints and unify architectures across domains. Despite these strides, many existing models still rely on separately trained components such as modality-specific encoders and decoders. In a new paper JetFormer: An Autoregressive Generative Model of Raw Images and Text, a Google DeepMind research team introduces JetFormer, a groundbreaking autoregre

@nrouter_ai1991nRouter's Model Catalog: RBAC Design where deny always takes precedenceLLMAPInrouterAIgateway0Posted at 2026-11-12nRouter's "Models" guide explains the specification of a searchable catalog (/models) that collects all available LLMs and multimodal models. Corresponding providers are cross-cloud, reflecting live availability, and all models can be accessed through a single endpoint and one virtual key (sk-nrouter-*). Viewing the catalog itsel

Those building or operating AI projects can hardly keep up with the rapid developments. The conference Mastering AI, organized by iX-Magazin, helps with orientation on 28th and 29th April 2027 in Karlsruhe. The Call for Proposals is open until 19th November 2026. Read more after the ad Mastering AI covers current topics such as Agentic AI, LLMs, multimodal models, computing infrastructure, and more. Equally important are safety, data protection, and regula
Published on June 16, 2026 at 5:48 PM Comment 2 𝕏 Print © Apple Initially, Apple planned a Siri update that would have brought some improvements in AI. After further consideration, the Cupertino-based company opted for a completely different strategy, namely a complete overhaul of Siri from A to Z. The least that can be said is that developing the new Siri has been no easy feat for Apple. Between the countless delays, certain engineers being sent on catch-

Shutterstock / Futurism Meta patented AI tech that constantly analyzes your voice and surroundings in order to detect your emotional state. Finally, exactly what we were all asking for: Meta being granted constant access to our offline lives. As first caught by Patentlyze, a patent published on July 2 describes a system that records all the user’s “audible communications” and combines it with “contextual factors” like “time of day, location, user activity,
Google was caught flat-footed by the sudden skyrocketing interest in generative AI despite its role in developing the underlying technology. This prompted the company to refocus its considerable resources on catching up to OpenAI. Since then, we’ve seen the detail-flubbing Bard and numerous versions of the multimodal Gemini models. While Gemini has struggled to make progress in benchmarks and user experience, that could be changing with the new 2.5 Pro (Ex
Changing the fundamental unit of RSI evolution from tasks to capabilities has the potential to move it from localized optimization for specific tasks toward continuous evolution across tasks and modalities.Recently, Shenzhen Infinite Recursion Intelligence Technology Co., Ltd. proposed The Trinity, an omnimodal, all-task recursive self-improvement framework that uses capabilities as its fundamental unit of evolution and drives the co-evolution of environme

Learning Modern Artificial Intelligence with PyTorch Kim Tae-hun | Hanbit Academy July 3, 2026 Why We Recommend This Book Readers can study the core theories of modern deep learning, from the fundamentals of neural networks to transformers and LLMs, implement them directly in PyTorch, and grow into an AI engineer with a practical focus through a personalized voice assistant project. View Details “I’ve built a few services with the LLM API. But I don’t know
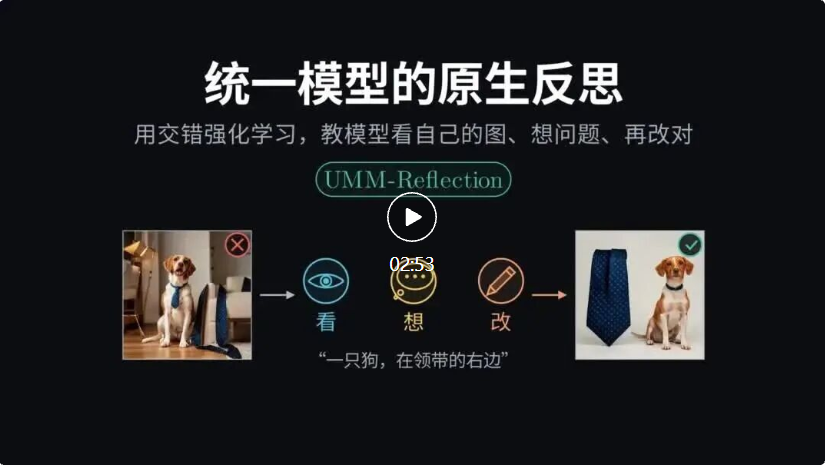
A unified multimodal model can both see images and generate them. So, can it, like a human, inspect its own work after generating it, identify problems, and then make revisions?Researchers from Nanyang Technological University, Shanghai Jiao Tong University, and the University of Tokyo have provided a positive answer. They introduced UMM-Reflection, using reinforcement learning to train complete multi-turn “reflection–revision” trajectories on the open-sou
The new model, which leverages 816 billion parameters and a 1 million token context window, claims to offer superior performance to other popular open-weight models, according to evaluation results released by Meta on Thursday. Muse Spark Open is natively multimodal and built for complex coding tasks and agentic labor. It has also been designed to run locally on Apple’s computers. However, you will still need a lot of power to run the model locally, with a

In 2004, Zhang Yimou captured an unforgettable water-sleeve drum dance in *House of Flying Daggers*. (Leifeng Network (official account: Leifeng Network)) The dancer portrayed by Zhang Ziyi stood at the center of a drum formation. Leaping and spinning to the music, she sent two long water sleeves billowing through the air, sometimes tracing immense arcs and sometimes whipping them toward the drums surrounding her. The performer's movements, the trajectory
Wen Le reporting from Aofeisi QbitAI | WeChat Official Account Hunyuan Hy4 has officially submitted its final answer! This time, Tencent came out swinging, making its ambition unmistakable:joining the ranks of the strongest open-source models. With 770B total parameters and 49B active parameters, it introduces native visual capabilities for the first time and supports computer operation for the first time. Instruction following, long-text comprehension, an
We’ve created GPT-4, the latest milestone in OpenAI’s effort in scaling up deep learning. GPT-4 is a large multimodal model (accepting image and text inputs, emitting text outputs) that, while less capable than humans in many real-world scenarios, exhibits human-level performance on various professional and academic benchmarks.