A unified multimodal model can both see images and generate them. So, can it, like a human, inspect its own work after generating it, identify problems, and then make revisions?
Researchers from Nanyang Technological University, Shanghai Jiao Tong University, and the University of Tokyo have provided a positive answer. They introduced UMM-Reflection, using reinforcement learning to train complete multi-turn “reflection–revision” trajectories on the open-source unified model BAGEL: the same model produces a diagnosis and then redraws the image based on that diagnosis, with no external scorer required at inference time.
After reinforcement learning, the model’s repair success rate on initially incorrect images increased from 20.6% to 64.9%, and its GenEval score rose from 0.72 with reflection SFT to 0.84, with the spatial positioning score jumping from 0.47 to 0.89. On WISE, which was unseen during training, it improved by 11 points—nearly 20 points higher than applying reinforcement learning directly to the generator. The code, model, and training data have all been open-sourced.
Paper title: Learning Native Reflection in Unified Models with Interleaved Reinforcement Learning
Paper link: https://arxiv.org/abs/2609.35767
Project page: https://waltstephen.github.io/UMM-Reflection/
Code: https://github.com/waltstephen/UMM-Reflection
Model and data: https://huggingface.co/collections/YijiaFan/umm-reflection-6ab95afe909092518d70a158
Authors: Yijia Fan*, Ziqi Huang*, Zhongang Cai, Yan Li, Zimo Wen, Wanqi Yin, Haiwen Diao, Ziwei Liu (*equal contribution; Ziwei Liu is the corresponding author)
Affiliations: Nanyang Technological University, Shanghai Jiao Tong University, University of Tokyo
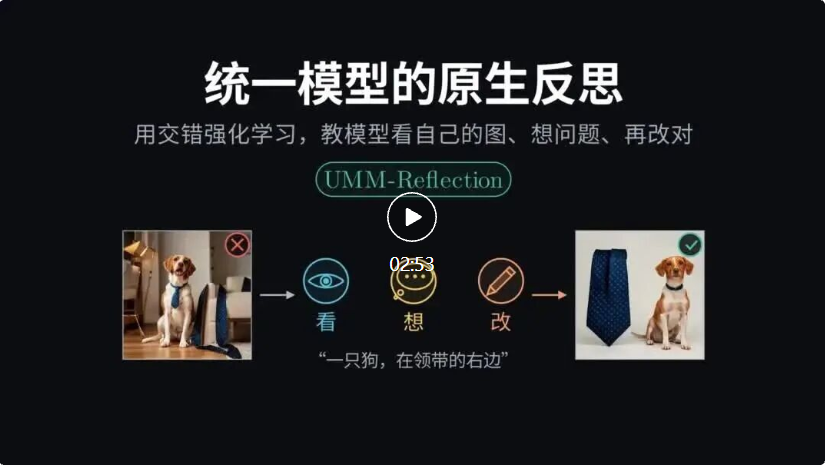
Video: Chinese-language explanation of UMM-Reflection (2 min 51 sec).
Key Results at a Glance
Repair success rate increased more than threefold: Among images that were initially generated incorrectly, the reflection SFT model could repair only 20.6%, while the reinforcement-learned model achieved 64.9%.
GenEval improved by 12 points (0.72→0.84): Spatial positioning improved from 0.47 to 0.89 (+42), color attribute binding by +14, and counting by +10. The three models had nearly identical initial-image accuracy, and all gains came from the reflection turns.
Transfer to benchmarks never seen during training: WISE 0.63→0.74, T2I-CompBench++ 0.50→0.55, OneIG 0.79→0.83.
Using the same RL budget to train the generator directly (direct text-to-image RL): GenEval only reached 0.76, and WISE performance was even lower than Base; UMM-Reflection outperformed it by 19.8 points on WISE.
Inference relies on no external critics or verifiers: viewing the image, diagnosing it, revising it, and deciding when to stop are all handled by the same model.
I. It can see and draw, but cannot revise its own images
As text instructions become increasingly complex, a single generated image often contains errors: reversed spatial relationships, incorrect counts, or colors assigned to the wrong objects. Traditional text-to-image models cannot perceive these errors, much less correct them. Unified multimodal models (UMMs) place visual understanding and image generation within a single network, theoretically allowing “a model that can draw” to “see images” as well, making it possible to reproduce the self-correction loop commonly found in large language models: inspect, diagnose, and revise.
Existing work has generally proceeded along two paths. One applies reinforcement learning to single-pass generation, such as first writing a textual plan and then generating an image, or using the model’s own understanding of the resulting image as a reward, but the model never goes back to revise what it has already generated. The other allows the model to continue reasoning and editing on intermediate images, but relies primarily on supervised imitation learning (SFT) of synthetic trajectories. Some work uses reinforcement learning to train multi-round regeneration, but each round is independent and does not inherit the preceding context.
The question researchers are investigating is: what exactly did imitation learning teach the model, and what is still missing?
II. Key observation: SFT learned to “revise,” but not to revise accurately
The researchers first constructed 29,529 multi-turn reflection trajectories and performed reflection SFT on BAGEL. The results showed that SFT learned far more than formatting: 95% of trajectories followed the reflection protocol, and when 16 trajectories were sampled for each initially erroneous image in the training set, 78% of the images had at least one correct repair path. In other words, effective revisions were already within the model’s capability range.
The problem was reliability. On a single-trajectory basis, the SFT model could correctly repair only 20.6% of the initially erroneous images. Three rounds of reflection yielded only about a 2-point improvement in total on GenEval and essentially plateaued after the first round. As shown in the upper left of Figure 1, SFT revisions often went in circles: first moving the tie, then the dog, and then moving the tie back, with the result still being wrong.
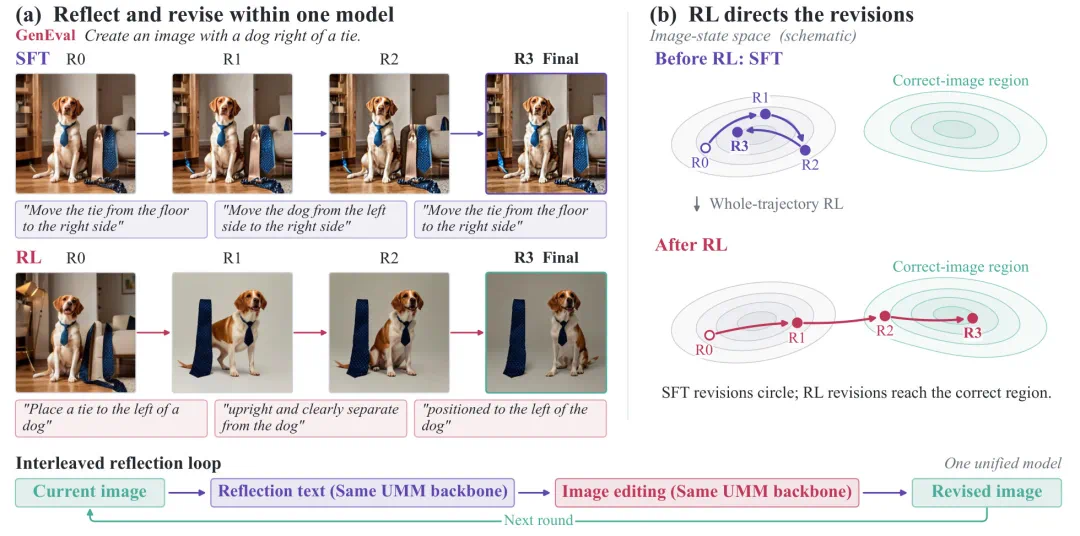
Figure 1: Comparison of reflection trajectories from SFT and RL under the same prompt and random seed. SFT can already produce meaningful revisions, but a single trajectory often circles back on itself; whole-trajectory RL focuses the policy on revision paths that can reach the “correct image region.”
This means that what is missing between being able to “revise” and revising correctly is an outcome-driven signal: whether a given reflection is useful can only be known after the image generation it triggers has been produced, or even after several more rounds.
III. Method: reinforcement learning over entire trajectories within a single model
The researchers call this multi-turn “inspection–diagnosis–revision” behavior performed by the unified model itself native reflection. Because the diagnostic text and revised image are produced by the same set of parameters—the text head writes the diagnosis, while the flow head re-renders the image according to it—the same outcome reward can update both along the same trajectory. Training is divided into two stages.
Stage 1: Cold-starting with reflection SFT.
At each turn, the model observes the original request, the entire preceding image-text history, and the current image; it outputs a structured reflection (THINKING / ACTION / EDIT) and chooses whether to continue editing or stop.Training data was synthesized by external models: GPT-5.5 served as the critic, while Qwen-Image and Qwen-Image-Edit handled generation and editing. BAGEL itself was excluded to avoid distilling its own failure modes back into the supervision signal. The data covers three types of trajectories: one-shot success, natural repair, and multi-step planning, and the prompts do not overlap with those in any evaluation benchmark.
Stage 2: Whole-Trajectory Reinforcement Learning.
There are two core designs:
(1)Sampling with a shared initial image. For each request, only one initial image is generated and detached from the computation graph, after which 16 complete reflection trajectories are sampled from that exact same image. Within-group relative advantages therefore compare the quality of different reflection strategies rather than which trajectory was lucky enough to receive a better initial image.
(2)One trajectory, one advantage. Each trajectory computes only a single outcome-driven advantage value, while all reflection tokens and flow generation steps within that trajectory are updated simultaneously. This avoids both the exponential rollout required for round-by-round credit assignment and the need to train an additional value model.
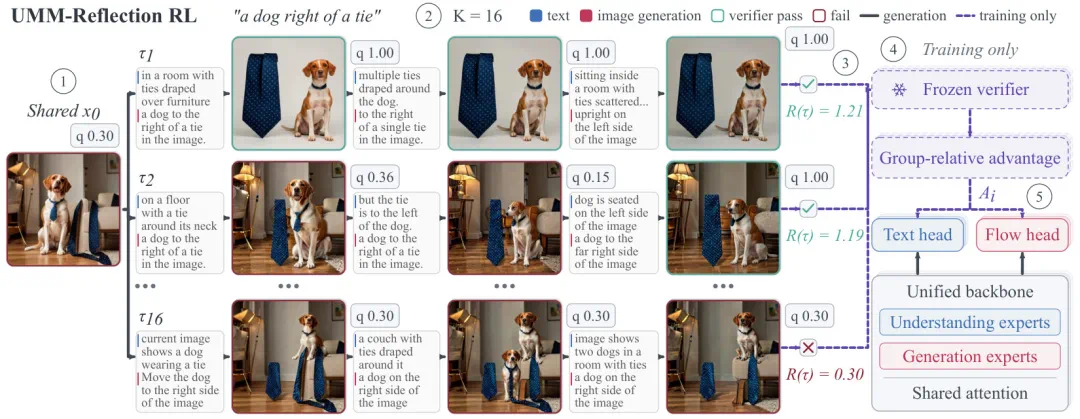
Figure 2: The reinforcement learning pipeline for UMM-Reflection. The 16 trajectories share the same initial image, and each trajectory alternates between the model’s own reflection and rendering for up to three rounds. A frozen verifier scores every image and trajectory; after within-group normalization, these scores produce a trajectory-level advantage, and the text and flow heads are updated simultaneously. The verifier is used only during training.
For rewards, the frozen verifier assigns each image a graded score between 0 and 1, allowing partial repairs to receive a nonzero progress signal. The trajectory reward jointly considers the final image quality, the magnitude of improvement in each round, and a penalty for “turning a correct result into an incorrect one.” The verifier is used only during training; at inference time, the model relies entirely on itself for reflection and stopping decisions.
4. Experiments: Improvements Focus on Reflection Rounds and Transfer to Unseen Benchmarks
All comparisons use the same BAGEL backbone, prompts, resolution, and scorer. RL is trained only on 3,000 prompts from the six GenEval task categories, while evaluation covers all 553 official GenEval prompts as well as WISE, OneIG-Bench, and T2I-CompBench++, which are never seen during training.
 Table 1: Main results under the same evaluation protocol (0–1).
On GenEval, UMM-Reflection improves over reflection SFT by 12 points. Spatial position, the category that depends most heavily on repairing the composition, rises from 0.47 to 0.89, while color attribute binding and counting improve by 14 and 10 points, respectively. Notably, the initial-image accuracies of Base, SFT, and RL are nearly identical (70–73). Since the initial generation itself receives no RL gradients, the gains come from the reflection rounds rather than from a better first image. Prompt-by-prompt paired statistics show that RL outperforms SFT on 109 prompts and trails on only 38 (McNemar’s test, p < 1e−8); when only the initial images are compared, there is no significant difference.
 Table 2: GenEval breakdown results (553 official prompts, 0–1).
On the three benchmarks never used during training, the same checkpoint still improves over reflection SFT by +11.0 on WISE, +4.6 on T2I-CompBench++, and +3.5 on OneIG. On OneIG, even SFT alone performs slightly below Base.
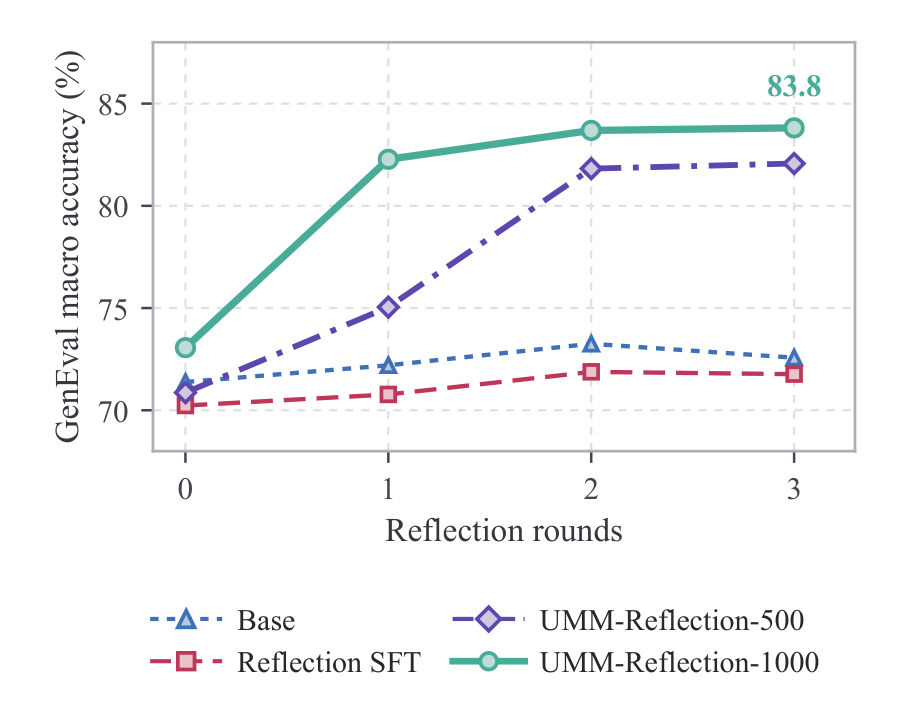
Figure 3: GenEval accuracy as a function of the number of reflection rounds. SFT gains approximately +2 points across three reflection rounds and plateaus after the first round; with RL, the first round alone yields approximately +9 points, with gains continuing through the third round.
From a test-time scaling perspective, the model’s conditional repair rate—the proportion of initially incorrect images that are ultimately repaired—rises from 20.6% to 64.9% after RL. The trade-off is that inference may require generating as many as four images, so the researchers also conducted a comparison under the same four-image budget.
5. Results
Below are the multi-turn reflection results of UMM-Reflection on four benchmarks. Each row shows, from left to right, the initial image followed by the revised results after the 1st, 2nd, and 3rd rounds of reflection. The model progressively corrects errors in spatial relationships, colors, materials, counts, and world knowledge.
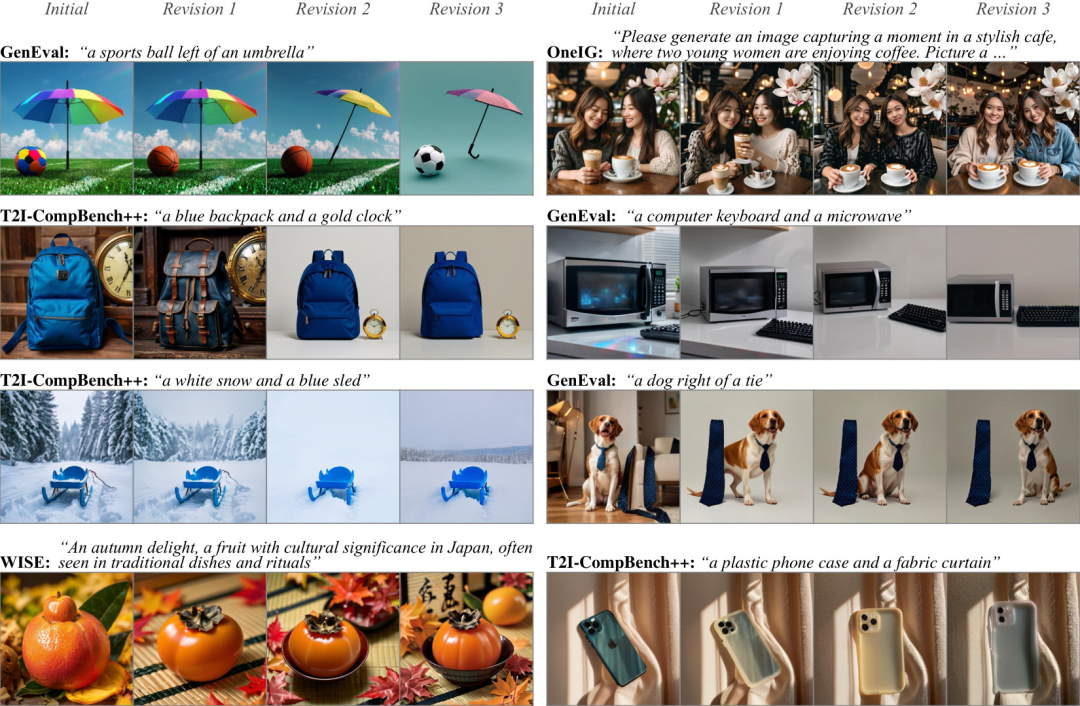
Figure 4: Reflection trajectories on the four benchmarks (initial image → revisions from rounds 1, 2, and 3).
6. Ablation: Training only the generator or only one head is not enough
A natural question is: What would happen if the same reinforcement-learning budget were spent directly on the generator? The researchers used the same 1,000 RL updates to directly optimize text-to-image generation (direct text-to-image RL). This raises the GenEval score for a single generation from 71 to 76, but it hardly transfers: WISE reaches only 54 (Base: 55), whereas UMM-Reflection reaches 84 and 74, respectively. The full ablation is shown in Table 3 in the paper.
 Table 3: GenEval ablation (0–100 scale). Initial: the accuracy of the first image; Final: the accuracy after reflection is complete; Repair rate: the proportion of initially incorrect images that are ultimately fixed.
Several comparisons point to the same conclusion: reflection SFT itself yields only a 2-point gain; training only the flow head or only the text head reaches just 73 and 78, respectively, while jointly optimizing the entire trajectory reaches 84. With the same four-image budget, selecting the best of four samples from the direct RL model reaches only 80, while forcing the SFT model to revise the image in every round reaches only 72. This shows that the gains do not come from “generating a few more images,” but from learning which revisions are genuinely effective.
7. What exactly does RL change in the model?
To understand the source of the gains, the researchers fed all 553 trajectories separately into the Base, SFT, and RL checkpoints and trained linear probes within the model to read out whether an image is correct. The results show that RL barely changes the model’s internal judgment of correctness: the probe AUC on the understanding branch remains between 0.80 and 0.82 at all three checkpoints.
What actually changes is where the image goes within this internal space. For initially incorrect images, the proportion that fall into the “correct region” after three rounds of reflection rises from 34% to 62% under RL, whereas under SFT it rises only from 36% to 42%. In other words, the model already “knows” whether its image is correct; what RL teaches it is to act on that knowledge: among the many revisions that SFT is already capable of producing, it selects the paths that truly push an incorrect image toward the correct region.
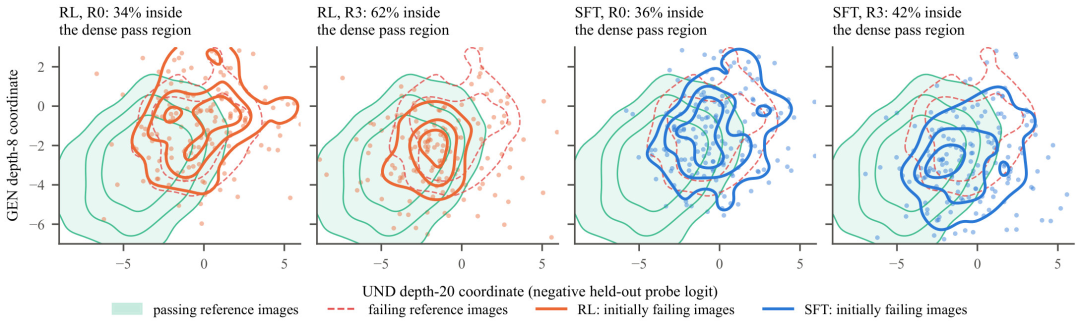
Figure 5: Trajectories of initially incorrect images in the model’s own correctness-readout space. The horizontal and vertical axes correspond to the linear-probe scores for “whether verification was passed” on the understanding and generation branches, respectively; the green region contains reference images that pass verification. The two panels on the left show RL from round 0 through round 3, and the two panels on the right show SFT.
8. Summary
This work shows that, for unified multimodal models, the paradigm of “SFT cold start + whole-trajectory RL,” which has been widely validated in LLM post-training, can also transfer to native multi-turn visual self-correction: SFT teaches the model the format of reflection and meaningful revisions, while RL makes those revisions reliable. Because inference does not rely on any external critic or verifier, the model performs image inspection, diagnosis, revision, and stopping on its own within a single context.
It should be noted that multi-turn reflection introduces additional inference overhead (generating up to 4 images); the rewards in the RL stage come from a GenEval-style compositional alignment verifier, and the training prompts cover only the six task categories in GenEval, leaving reward signals across more dimensions to be explored. The research team has open-sourced all training and evaluation code, the RL and SFT model weights, and the SFT data, with the hope of providing a reproducible starting point for research on reflection and reinforcement learning in unified models.